es

The Wolfram Mathematica notebook which contains the code that produces all the Mathematica output in this web page may be downloaded at this link. Caution: This notebook will evaluate, cell-by-cell, sequentially, from top to bottom. However, due to re-use of variable names in later evaluations, once subsequent code is evaluated prior code may not render properly. Returning to and re-evaluating the first Clear[ ] expression above the expression no longer working and evaluating from that point through to the expression solves this problem.

$Post := If[MatrixQ[#1], MatrixForm[#1], #1] & (* outputs matrices in MatrixForm*)
Remove[ "Global`*"] // Quiet (* remove all variables *)
In this section, we consider vector spaces over one of the following two fields: either ℝ, a set of real numbers or ℂ, a set of complex numbers. To enhance pedagogical effectiveness, the treatment of the dot product is presented in several distinct sections:

Orthogonality

Gram--Schmidt Process

Positive definite

Curvilinear coordinates

Solvability

Inner Product

An inner product of two vectors, usually denoted by \( \left\langle {\bf x} , {\bf y} \right\rangle ,\) or ⟨ x∣y ⟩ is a generalization of the dot product for complex spaces and abstract vector spaces. The inner product spaces establishes a bridge between abstract algebra and physical geometry. They inject the real-world concepts of distance, angle, and perpendicularity into highly abstract mathematical environments.

Let V be a vector space over field 𝔽. A mapping ⟨·,·⟩ : V × V → 𝔽 (field 𝔽 is either ℝ or ℂ) is called an inner product if it satisfies the following axioms.
  1. \( \displaystyle \quad \langle \mathbf{x} , \mathbf{y} \rangle = \overline{\langle \mathbf{y} , \mathbf{x} \rangle} = \langle \mathbf{y} , \mathbf{x} \rangle^{\ast} , \quad \) complex conjugate (usually it is denoted either by overline or asterisk).
  2. ⟨x , x⟩ ≥ 0 for all x ∈ V and equals zero if and only if x = 0.
  3. ⟨αx + βy , z⟩ = α✶⟨x , z⟩ + β✶⟨y , z⟩ whenever α, β ∈ 𝔽.
A vector space together with the inner product is called an inner product space.
Note that the latter axiom implies ⟨x , αy + βz⟩ = α⟨x , y⟩ + β⟨x , z⟩. A friendly reminder: \( \overline{\bf x} = \overline{a + {\bf j}\, b} = a - {\bf j}\,b = {\bf x}^{\ast} \quad \) is a complex conjugate of a complex number x = a + ⅉb. Remember that there is no universal notation for the imaginary unit, which we prefer to denote as ⅉ or j, with ⅉ² = −1.

In ℂⁿ (complex space), the standard inner product of two vectors x and y is defined by taking the complex conjugate (indicated by an overline \( \displaystyle \ \overline{z}\ \) or asterisk z✶) of the components of the first vector:

\begin{equation} \label{EqInner.1} \langle \mathbf{x}, \mathbf{y} \rangle = \sum_{k=1}^n \, \overline{x_k}\,y_k = \sum_{k=1}^n \, x_k^{\ast} y_k = x_1^{\ast} y_1 + x_2^{\ast} y_2 + \cdots + x_n^{\ast} y_n . \end{equation}

Note that some authors from the West Coast flip this convention and apply the complex conjugate operation on the second vector:
\[ \langle \mathbf{x}, \mathbf{y} \rangle = \sum_{k=1}^n \, x_k\,\overline{y_k} = \sum_{k=1}^n \, x_k\, y_k^{\ast} = x_1\, y_1^{\ast} + x_2 \, y_2^{\ast} + \cdots + x_n \, y_n^{\ast} . \]

Why do we need the conjugate? Consider a 1-dimensional complex vector x = [ⅉ]. If we used the normal dot product formula to find its length squared (⟨ x , x ⟩), we would get:
\[ ⅉ \bullet ⅉ = ⅉ^2 = -1 . \]
A vector cannot have a negative "length squared." By using the complex conjugate in the inner product, we fix this:
\[ \langle \mathbf{x} , \mathbf{x} \rangle = ⅉ^{\ast} \bullet ⅉ = (ⅉ) \cdot ⅉ = - ⅉ^2 = 1 . \]
Because of the conjugate requirement, three major algebraic behaviors shift when compared to real dot products:
  1. Symmetry becomes "Conjugate Symmetry".
    • By definition, the dot product is symmetric, x • y = y • y.
    • In complex space: ⟨ x , y ⟩ = ⟨ y , x ⟩✶.
    • If you swap the order of the vectors in a complex inner product, you must conjugate the final result.
  2. Linearity is asymmetric (Pulling out constants). When you pull a scalar constant α out of an inner product, its behavior depends entirely on which slot it is in:
    • Second Slot: Linear. It pulls out perfectly normally: ⟨ x , αy ⟩ = α ⟨ x , y ⟩.
    • First Slot: Conjugate-linear. It pulls out as a conjugate: ⟨ αx , y ⟩ = α✶⟨ x , y ⟩.
  3. Norm (Length) calculation. The norm is always calculated by taking the inner product of a vector with itself. Because of conjugate symmetry, is always a real, non-negative number, allowing length to remain intuitive:
    \begin{equation} \label{EqInner.2} \| {\bf u} \| = +\sqrt{\left\langle {\bf u} , {\bf u} \right\rangle} = + \left( \left\langle {\bf u} , {\bf u} \right\rangle \right)^{1/2} . \end{equation}
   
Example 1: The most critical trap when dealing with complex vector spaces in Mathematica is that the standard operators do not automatically apply a complex conjugate. They compute bilinear algebraic products, not geometric inner products. There are three core commands for evaluation of the inner products:
  1. "x . y" (The Matrix/Vector Dot Operator).
    • Behavior: Computes the standard distributive sum of products: \( \displaystyle \quad \sum_i \,x_i y_i . \)
            {1, 2} . {3, 4}
            11
    • Complex Case Trap: It does not conjugate the first vector. To get a valid complex inner product, you must explicitly write Conjugate[x] . y.
            {1 + I, 3 - I} . {2 - 3*I, 4}
            17 - 5 I
  2. Dot[x, y]
    • Behavior: This is the exact functional equivalent of the " . " operator (x . y is just syntactic sugar for Dot[x, y]).
            Dot[{1, 2} , {3, 4}]
            11
    • Complex Case Trap: Exactly like " . " above, it performs no complex conjugation.
            Dot[{1 + I, 3 - I} , {2 - 3*I, 4}]
            17 - 5 I
  3. Inner[f, x, y, g] (The Generalized Tensor Operator).
    • Behavior: A highly flexible function that replaces the multiplication step with a custom function f, and the summation step with a custom function g. The syntax is Inner[multiplication_func, x, y, addition_func].
            Inner[Times, {1, 2}, {3, 4} , Plus]
            11
    • Complex Case Advantage: By changing the multiplication function to a custom conjugating rule, Inner can be forced to compute a true geometric complex inner product in a single, elegant step without needing to wrap the input vector manually.
            Inner[Conjugate[#1]*#2 &, {1 + I, 3 - I} , {2 - 3*I, 4}, Plus]
            11 - I
We summarize Mathematica Verification Script.
(* Clear notebook workspace *) ClearAll[xVec, yVec, stdDot, standardDotFunc, customInnerProduct]; (* 1. Define two non-trivial complex vectors *) xVec = {1 + I, 2*I}; yVec = {3, 1 - 2*I}; (* 2. Execute Command 1: The standard dot operator *) (* Note: This does NOT conjugate *) dotOperatorResult = xVec . yVec; (* 3. Execute Command 2: The functional Dot command *) (* This matches xVec . yVec identically *) dotFunctionResult = Dot[xVec, yVec]; (* 4. Execute Command 3: The generalized Inner command *) (* We pass a custom function that conjugates the element from the first slot *) (* syntax: Inner[ element_multiplier, vector1, vector2, accumulator ] *) innerProductResult = Inner[Conjugate[#1]*#2 &, xVec, yVec, Plus]; (* 5. Print a comprehensive evaluation sheet for students *) Print["=== MATHEMATICA COMPLEX VECTOR OPERATION COMPARISON ==="]; Print["Vector x = ", xVec]; Print["Vector y = ", yVec]; Print[""]; Print["1. Using [ x . y ] operator: ", dotOperatorResult]; Print["2. Using [ Dot[x, y] ] function: ", dotFunctionResult]; Print["3. Using Custom [ Inner[...] ]: ", innerProductResult]; Print[""]; Print["=== THE GEOMETRIC COMPLEX INNER PRODUCT TEST ==="]; Print["True geometric inner product via manual conjugation [ Conjugate[x] . y ]: " , Conjugate[xVec] . yVec]; Print["Does our custom Inner[...] call match the true geometric inner product? ", innerProductResult == (Conjugate[xVec] . yVec) ];
   ■
End of Example 1

The second axiom (known as the positive-definite condition) leads to the following definition.

A vector space X is said to be a normed linear space if there exists a nonnegative function, denoted by ∥·∥ : X → [0, ∞), that satisfies the following axioms.
  1. ∥x∥ ≥ 0 for all x ∈ X and ∥x∥ = 0 if and only if x = 0.
  2. ∥αx∥ = |α| ∥x∥ for all α ∈ 𝔽.
  3. ∥x + y∥ ≤ ∥x∥ + ∥y∥.
Once an inner product is defined, we immediately gain access to three critical geometric concepts:
  • Norm (Length): The length of a vector is the square root of its inner product with itself,
    \[ \| {\bf u} \| = +\sqrt{\left\langle {\bf u} , {\bf u} \right\rangle} = + \left( \left\langle {\bf u} , {\bf u} \right\rangle \right)^{1/2} . \tag{2} \]
  • Distance: The structural spacing separating two distinct vector states.
    \[ d \left( \mathbf{u} , \mathbf{v} \right) = \| {\bf u} - \mathbf{v} \| = +\sqrt{\left\langle {\bf u} - \mathbf{v}, {\bf u} - \mathbf{v} \right\rangle} . \]
    Every inner product space is a metric space.
  • Orthogonality (Perpendicularity): Two vectors are orthogonal if their intersection drops to zero.
    \[ \mathbf{u} \perp \mathbf{v} \qquad \iff \qquad \left\langle {\bf u} , \mathbf{v} \right\rangle = 0 . . \]
   
Example 2: Mathematica handles vector norms through its built-in Norm function, which easily adapts to compute different types of geometric and algebraic norms. By default, Norm[x] computes the standard Euclidean norm (𝔏² norm). However, you can pass a second argument to compute the general 𝔏ᵖ norm, or use specialized matrix layouts to evaluate custom Deformation Metric Norms.

The core Norm implementations:

  1. The Euclidean Norm (𝔏² Norm)
    • Mathematical Form: \( \displaystyle \quad \| \mathbf{x} \|_2 = +\sqrt{\sum_i \,|x_i |^2} . \)
    • Mathematica Syntax: Norm[x] or Norm[x, 2]
  2. The Taxicab / Manhattan Norm (𝔏¹ Norm)
    • Mathematical Form: \( \displaystyle \quad \| \mathbf{x} \|_1 = \sum_{i=1}^n \,| x_i | . \)
    • Mathematica Syntax: Norm[x, 1]
  3. The Max / Infinity Norm (𝔏∞ Norm)
    • Mathematical Form:\( \displaystyle \quad \| \mathbf{x} \|_{\infty} = \max\left\{ | x_i | \right\} . \)
    • Mathematica Syntax: Norm[x, Infinity]
  4. The Custom Deformation Norm (M Norm).
    • Mathematical Form: \( \displaystyle \quad \| \mathbf{x} \|_{M} = + \sqrt{\langla \mathbf{x} , \mathbf{x} \rangle}_M = +\sqrt{\mathbf{x}^{\ast} \mathbf{M}\,\mathbf{x}} . \)
    • Mathematica Syntax: Sqrt[Conjugate[x] . M . x]
(* Clear notebook environment *) ClearAll[xVec, matM, l1Norm, l2Norm, lInfNorm, customNorm]; (* 1. Define a non-trivial complex vector *) xVec = {3 - 4*I, 1 + I}; (* 2. Define a positive-definite metric matrix M for a deformation norm *) matM = {{2, 0}, {0, 3}}; (* 3. Compute the standard p-norms *) l1Norm = Norm[xVec, 1]; l2Norm = Norm[xVec]; (* Default is p=2 *) lInfNorm = Norm[xVec, Infinity]; (* 4. Compute the custom deformation norm generated by matrix M *) customNorm = Sqrt[ (Conjugate[xVec] . matM) . xVec ]; (* 5. Print a clean summary sheet for students *) Print["=== MATHEMATICA NORM EVALUATION CHEATSHEET ==="]; Print["Vector x = ", xVec]; Print[""]; Print["1. Taxicab Norm (L1): ", l1Norm]; Print[" Numerical Approximation: ", N[l1Norm]]; Print[""]; Print["2. Euclidean Norm (L2): ", l2Norm]; Print[" Numerical Approximation: ", N[l2Norm]]; Print[""]; Print["3. Infinity Norm (L_infinity): ", lInfNorm]; Print[" Numerical Approximation: ", N[lInfNorm]]; Print[""]; Print["4. Custom Deformation Norm (M): ", customNorm]; Print[" Numerical Approximation: ", N[customNorm]];

Taking a vector \( {\bf v} = \left( 2, {\bf j} , -2 \right) , \) we calculate norms:

Norm[{2, \[ImaginaryJ], -2}]
Norm[{2, \[ImaginaryJ], -2}, 3/2]
Out[1]= 3
Out[2]= (1 + 4 Sqrt[2])^(2/3)

To find the Euclidean norm (also called the 𝔏² norm or geometric length) of a complex vector, you cannot simply square and add the raw components, because squaring a complex number can yield a negative or complex result. Instead, you must multiply each component by its complex conjugate. This guarantees that the magnitude of each component is a non-negative real number. Therefore,

\[ \| \mathbf{z} \|_2 = +\sqrt{| z_1 |^2 + | z_2 |^2 + \cdots + |z_n |^2} \]
where \( \displaystyle \quad | z_i |^2 = z_i^{\ast} z_i \quad \) because |𝑎 + bⅉ|^2 = 𝑎² + b².

Let's find the Euclidean norm of the non-trivial complex vector: z = [3 − 4ⅉ, 1 + ⅉ]. First, we compute the magnitude squared of each component

\begin{align*} | 3 - 44ⅉ|^2 &= 3^2 + 4^2 = 25 , \\ | 1 + ⅉ|^2 &= 1^2 + 1^2 = 2 . \end{align*}
Adding the magnitudes squared, we get
\[ \| \mathbf{z} \|_2^2 = 2 + 25 = 27 . \]
Taking the square root, we obtain \( \displaystyle \quad \| \mathbf{z} \|_2 = \sqrt{27} \approx 5.19615 . \)
(* Clear local variables *) ClearAll[xVec]; (* Define the complex vector *) xVec = {3 - 4*I, 1 + I}; (* Method 1: Using the built-in Norm function (Default is Euclidean) *) normMethod1 = Norm[xVec]; (* Method 2: Vector inner product definition (Conjugate Transpose Dot Vector) *) normMethod2 = Sqrt[Conjugate[xVec] . xVec]; (* Print Results *) Print["Exact Euclidean Norm: ", normMethod1]; Print["Numerical Approximation: ", N[normMethod1]]; Print["Do both methods match? ", normMethod1 == normMethod2];
   ■
End of Example 2
Theorem 1: For an inner product space, the formula ∥x∥ = ⟨ x , x ⟩½ does specify a norm.

All the axioms are obvious except the triangle inequality. To verify this, we evaluate \begin{align*} \| \mathbf{x} + \mathbf{y} \|^2 &\equiv \langle \mathbf{x} + \mathbf{y} , \mathbf{x} + \mathbf{y} \rangle \equiv \| \mathbf{x} \|^2 + \| \mathbf{y} \|^2 + 2\,\Re\,\langla \mathbf{x} , \mathbf{y} \rangle \\ & \le \| \mathbf{x} \|^2 + \| \mathbf{y} \|^2 + 2\,|\langle \mathbf{x} , \mathbf{y} \rangle | \\ &\le \| \mathbf{x} \|^2 + \| \mathbf{y} \|^2 + 2\,\| \mathbf{x} \| \, \| \mathbf{y} \| \\ &= \left( \| \mathbf{x} \| + \| \mathbf{y} \| \right)^2 . \end{align*}
   
Example 3: Let us consider three vectors:
\[ \mathbf{u} = \begin{pmatrix} \mathbf{j} \\ 1 \end{pmatrix} , \quad \mathbf{v} = \begin{pmatrix} 1 \\ \mathbf{j} \end{pmatrix} , \quad \mathbf{w} = \begin{pmatrix} 3 - 5\mathbf{j} \\ 1 + 2\mathbf{j} \end{pmatrix} . \]
First, we find their norms:
\begin{align*} \| \mathbf{u} \|^2 &= \begin{pmatrix} \mathbf{j} \\ 1 \end{pmatrix}^{\ast} \begin{pmatrix} \mathbf{j} \\ 1 \end{pmatrix} = 1^2 + 1^2 = 2 , \\ \| \mathbf{v} \|^2 &= \begin{pmatrix} 1 \\ \mathbf{j} \end{pmatrix}^{\ast} \begin{pmatrix} 1 \\ \mathbf{j} \end{pmatrix} = 2 , \\ \|\mathbf{w} \|^2 &= \begin{pmatrix} 3 - 5\mathbf{j} \\ 1 + 2\mathbf{j} \end{pmatrix}^{\ast} \begin{pmatrix} 3 - 5\mathbf{j} \\ 1 + 2\mathbf{j} \end{pmatrix} = 3^2 + 5^2 + 1^2 + 2^2 = 39 . \end{align*}
u = {I, 1}; Norm[u]
Sqrt[2]
Norm[{{3 - 5*I, 1 + 2*I}}]
Sqrt[39]
Then we calculate their inner products:
\begin{align*} \langle \mathbf{u} , \mathbf{v} \rangle^2 &= \mathbf{u}^{\ast} \mathbf{v} = -\mathbf{j} + \mathbf{j} = 0 , \\ \langle \mathbf{u} , \mathbf{w} \rangle^2 &= \mathbf{u}^{\ast} \mathbf{w} = -3\mathbf{j}-5 + 1 + 2\mathbf{j} = -4 - \mathbf{j} , \\ \langle \mathbf{v} , \mathbf{w} \rangle^2 &= \mathbf{v}^{\ast} \mathbf{w} = 3 - 5\mathbf{j} - \mathbf{j} + 2 = 5 -6\mathbf{j} . \end{align*}
Inner[Conjugate[#1]*#2 &, {1 , I} , {3 - 5*I, 1 + 2*I}, Plus]
5 - 6 I
   ■
End of Example 3

With dot product in real vector space, we can assign a length of a vector, which is also called the Euclidean norm or 2-norm:

\[ \| {\bf x} \|_2 = \| {\bf x} \| = \sqrt{ {\bf x}\cdot {\bf x}} = \sqrt{x_1^2 + x_2^2 + \cdots + x_n^2} . \]
In complex space, the inner product expands this definition of the Euclidean norm norm:
\[ \| {\bf x} \|_2 = \| {\bf x} \| = \sqrt{ \langle {\bf x} , {\bf x} \rangle} = \sqrt{| x_1 |^2 + |x_2 |^2 + \cdots + |x_n |^2} . \]
This norm can be generalized for arbitrary real p > 1:
\[ \| {\bf x} \|_p = \left( |x_1 |^p + |x_2 |^p + \cdots + |x_n |^p \right)^{1/p} . \]
Example 4: In the set of integrable functions on an interval [a,b], we can define the inner product of two functions f and g as
\[ \left\langle f , g \right\rangle = \int_a^b \overline{f} (x)\, g(x) \, {\text d}x \qquad\mbox{or} \qquad \left\langle f , g \right\rangle = \int_a^b f(x)\,\overline{g} (x) \, {\text d}x . \]
Then the norm \( \| f \| \) (also called the 2-norm or 𝔏² norm) becomes the square root of
\[ \| f \|^2 = \left\langle f , f \right\rangle = \int_a^b \left\vert f(x) \right\vert^2 \, {\text d}x . \]
In particular, the 2-norm of the function \( f(x) = 5x^2 +2x -1 \) on the interval [0,1] is
\[ \| 2 x^2 +2x -1 \| = \sqrt{\int_0^1 \left( 5x^2 +2x -1 \right)^2 {\text d}x } = \sqrt{7} . \]

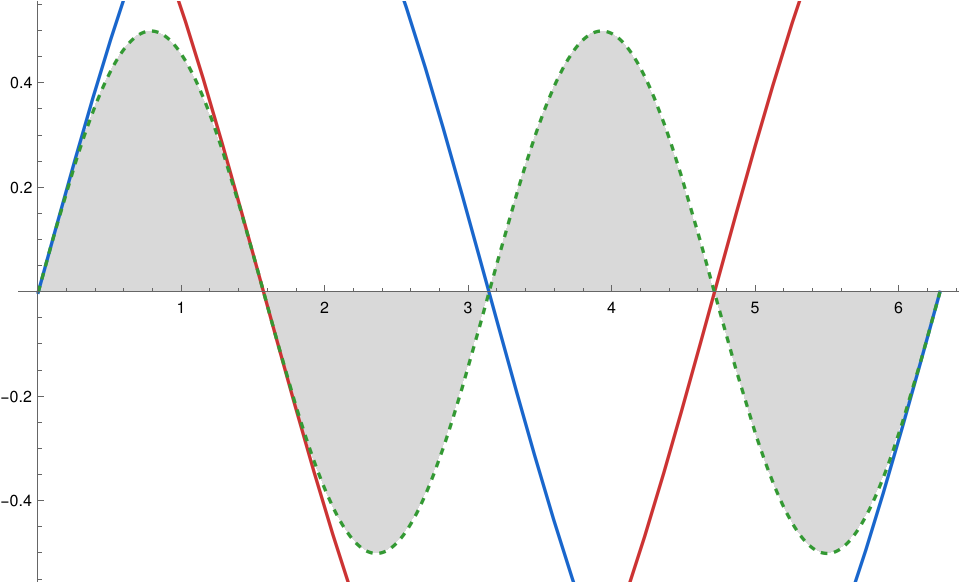
The follwoing Mathematica script plots f(x) = sin(x) and g(x) = cos(x) on the interval [0, 2π], along with their product f(x) g(x) = sin(x) cos(x). It shades the area under the product curve to visually demonstrate how the positive and negative regions perfectly cancel out, proving that the inner product integral\( \displaystyle \quad \int_0^{2\pi}\,\sin (x)\,\cos (x)\,{\text d}x = 0 . \) .

ClearAll[f, g, productPlot, curvePlot]; f[x_] := Sin[x]; g[x_] := Cos[x]; (* 1. Create the filled region for the product curve to show cancellation *) productPlot = Plot[f[x] g[x], {x, 0, 2 \[Pi]}, PlotStyle -> None, Filling -> Axis, FillingStyle -> Directive[Opacity[0.25], GrayLevel[0.4]], Exclusions -> None ]; (* 2. Create the main curves with distinct styles and labels *) curvePlot = Plot[{f[x], g[x], f[x] g[x]}, {x, 0, 2 \[Pi]}, PlotStyle -> { Directive[Thick, RGBColor[0.1, 0.4, 0.8]], (* f(x) Blue *) Directive[Thick, RGBColor[0.8, 0.2, 0.2]], (* g(x) Red *) Directive[Thick, Dashed, RGBColor[0.2, 0.6, 0.2]] (* f(x)g(x) Green *) }, PlotLegends -> Placed[ Expressions, Below ], AxesLabel -> {"x", "y"}, Ticks -> {{0, \[Pi]/2, \[Pi], 3 \[Pi]/2, 2 \[Pi]}, Automatic}, PlotLabel -> Style["Orthogonality of Sin(x) and Cos(x) on [0, 2\[Pi]]", 14, Bold], GridLines -> {{0, \[Pi]/2, \[Pi], 3 \[Pi]/2, 2 \[Pi]}, {0}}, GridLinesStyle -> Directive[GrayLevel[0.8], Dashed], Method -> {"AxesInFront" -> False} ]; (* 3. Combine plots cleanly without any legacy layout wrapper restrictions *) Show[productPlot, curvePlot, ImageSize -> Large]
Figure 3.1: Inner product of sine and cosine functions.

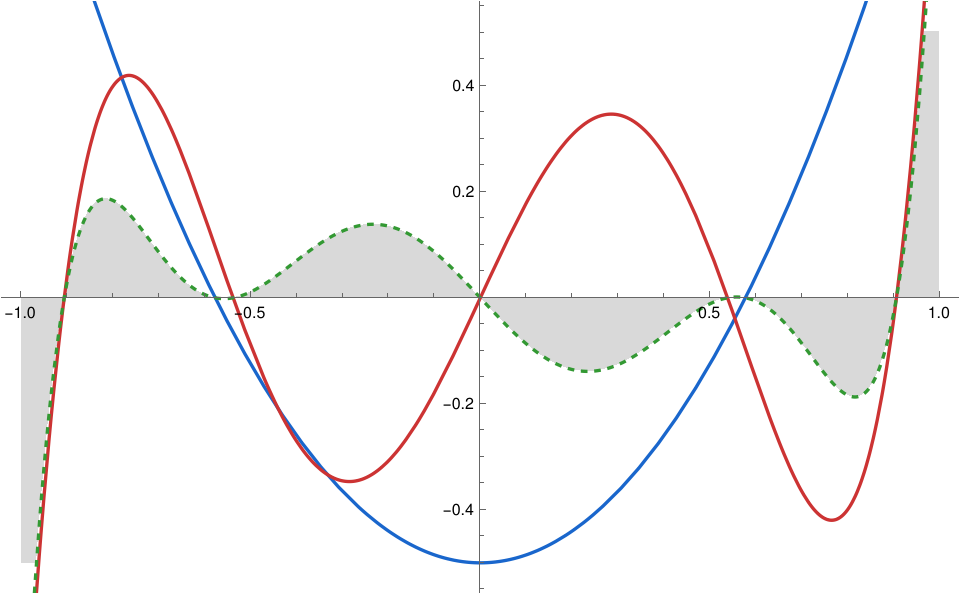
As another example, we consider two Legendre polynomials P₂(x) = (3x² −1)/2 and P₅(x) = (63x⁵ − 70x³ + 15x)/8.

ClearAll[p2, p5, productPlot, curvePlot]; (* Define the Legendre Polynomials explicitly or via LegendreP *) p2[x_] := LegendreP[2, x]; (* 1/2(3x^2 - 1) *) p5[x_] := LegendreP[5, x]; (* 1/8(63x^5 - 70x^3 + 15x) *) (* 1. Shading for the product curve to visually demonstrate net-zero area *) productPlot = Plot[p2[x] p5[x], {x, -1, 1}, PlotStyle -> None, Filling -> Axis, FillingStyle -> Directive[Opacity[0.25], GrayLevel[0.4]], Exclusions -> None ]; (* 2. Core structural plotting setup *) curvePlot = Plot[{p2[x], p5[x], p2[x] p5[x]}, {x, -1, 1}, PlotStyle -> { Directive[Thick, RGBColor[0.1, 0.4, 0.8]], (* P2(x) Blue *) Directive[Thick, RGBColor[0.8, 0.2, 0.2]], (* P5(x) Red *) Directive[Thick, Dashed, RGBColor[0.2, 0.6, 0.2]] (* Product Green *) }, PlotLegends -> Placed[ {"P2(x)", "P5(x)", "P2(x) * P5(x)"}, Below ], AxesLabel -> {"x", "y"}, PlotLabel -> Style["Orthogonality of Legendre Polynomials on [-1, 1]", 14, Bold], GridLines -> {Automatic, {0}}, GridLinesStyle -> Directive[GrayLevel[0.8], Dashed], Method -> {"AxesInFront" -> False} ]; (* 3. Render combined layer graphics cleanly *) Show[productPlot, curvePlot, ImageSize -> Large]
Figure 3.1: Inner product of Legandre polynomials.
Use code with caution. 💡 Pedagogical Discussion Points for the Webnotes: The Integration Symmetries: If you look at the dashed green product curve, it is an odd function over a symmetric interval . Because is an even function (degree 2) and is an odd function (degree 5), their product is structurally odd. Instant Evaluation: This gives students an immediate visual intuition for why holds true—the left side of the y-axis contains equal and opposite area weights compared to the right side, forcing the inner product to balance to zero. Would you like to add a text snippet for your notes showing how to perform the formal Gram-Schmidt process step-by-step to construct these polynomials starting from standard basis elements , or are there other Linear Algebra core theorems you need code for? AI responses may include mistakes. Learn more Skip to previous prompt Use code with caution. 💡 Visual Classroom Talking Points: The Balancing Act: Point out the shaded green dashed curve ( ). There are two identical positive bumps and two identical negative bumps. Geometric Integration: Show students that when taking the functional inner product , the net shaded area under that dashed curve is exactly zero, which is the definition of abstract orthogonality. If you want to customize your webnotes or code further, let me know: Do you want a similar plot for Legendre polynomials (like and ) on ? Would you like the code to compute and display the numerical integration value automatically alongside the plot? AI responses may include mistakes. Learn more Skip to previous prompt    ■
End of Example 4
         
 Augustin-Louis Cauchy    Viktor Yakovlevich Bunyakovsky    Hermann Amandus Schwarz

Theorem 2 (Cauchy--Bunyakovsky--Schwarz inequality): Let V be a complex inner product space. For any vector x, y ∈ V the Cauchy--Bunyakovsky--Schwarz (or simply CBS) inequality holds:
\[ | \langle {\bf x} , {\bf y} \rangle | \le \| {\bf x} \| \, \| {\bf y} \| \quad \iff \quad | \langle {\bf x} , {\bf y} \rangle |^2 \le \langle \mathbf{x} , \mathbf{x} \rangle \cdot \langle \mathbf{y} , \mathbf{y} \rangle , \]
where ∥x∥, ∥y∥ are 2-norms defined in Eq.\eqref{EqInner.2}.

The CBS inequality becomes a strict equality if and only if the two vectors are linearly dependent.
The inequality for sums was published by the French mathematician and physicist Augustin-Louis Cauchy (1789--1857) in 1821, while the corresponding inequality for integrals was first proved by the Russian mathematician Viktor Yakovlevich Bunyakovsky (1804--1889) in 1859. The modern proof is based on mathematical trick that was given by the German mathematician Hermann Amandus Schwarz (1843--1921) in 1888.

The Proof is based on Schwarz's approach, which he published in 1885. Step 1: Handle the Trivial Case:

If y = 0, then ⟨x , 0*rang; = 0 and ∥0∥ = 0. Both sides of the inequality become 0, so the inequality holds trivially as 0 ≤ 0. For the rest of the proof, we assume y ≠ 0.

Step 2: Set up a Non-Negative Vector w. One of the defining axioms of any inner product space is Positive Definiteness: the inner product of any vector with itself must be greater than or equal to zero. Following Schwarz's logic, let us construct a new vector using a complex scalar parameter t. To make the algebra align cleanly with complex numbers, we set up the vector as:

\[ \mathbf{w} = \mathbf{x} -t\,\mathbf{y} , \qquad \mathbf{y} \ne 0 . \]
By the positivity axiom, we know that
\[ \langle \mathbf{w} , \mathbf{w} \rangle \ge 0 \quad \iff \quad \langle \mathbf{x}- t\,\mathbf{y} , \mathbf{x} -t\,\mathbf{y} \rangle \ge 0 . \]
Step 3: Expand the Inner Product. Using the linearity of the first slot and the conjugate-linearity of the second slot, we expand this expression step-by-step:
\[ \langle \mathbf{x} , \mathbf{x} \rangle - \langle \mathbf{x} , t\,\mathbf{y} \rangle - \langle t\,\mathbf{y} , \mathbf{x} \rangle + \langle t\,\mathbf{y} , t\,\mathbf{y} \rangle \ge 0 . \]
Pull out the scalar t (remembering to conjugate it if it comes from the first slot):
\[ \| \mathbf{x} \|^2 - t\,\langle \mathbf{x} , \mathbf{y} \rangle - t^{\ast}\langle \mathbf{y} , \mathbf{x} \rangle + t^{\ast} t\,\|\mathbf{y} \|^2 \ge 0 . \]
Using the property that t✶t = |t|² and conjugate symmetry ⟨u, v⟩ = ⟨v, u⟩✶, we get
\[ \| \mathbf{x} \|^2 - t\,\langle \mathbf{x} , \mathbf{y} \rangle - t^{\ast}\langle \mathbf{x} , \mathbf{y} \rangle^{\ast} + |t|^{2} \,\|\mathbf{y} \|^2 \ge 0 . \]
Step 4: Choose the Optimal t. Schwarz's method works for any choice of t. To make the unwanted terms collapse and isolate our target terms, we intentionally pick a smart value for t. Let:
\[ t = \frac{\langle \mathbf{x} , \mathbf{y} \rangle}{\| \mathbf{y} \|^2} . \]
This is valid because we assumed y ≠ 0, meaning ∥y∥ > 0.) Now substitute this specific t back into our expanded inequality:
\[ \| \mathbf{x} \|^2 - \left( \frac{\langle \mathbf{x} , \mathbf{y} \rangle}{\| \mathbf{y} \|^2} \right) \langle \mathbf{x} , \mathbf{y} \rangle - \left( \frac{\langle \mathbf{x} , \mathbf{y} \rangle}{\| \mathbf{y} \|^2} \right)^{\ast} \langle \mathbf{x} , \mathbf{y} \rangle^{\ast} + \left\vert \frac{\langle \mathbf{x} , \mathbf{y} \rangle}{\| \mathbf{y} \|^2} \right\vert^2 \| \mathbf{y} \|^2 \ge 0 . \]
Step 5: Simplify to the Final Result. Recall that for any complex number z, we have z z✶ = z✶z = |z|^2. Therefore, ⟨x, y⟩ ⟨x, y⟩✶ = |⟨x, y⟩|². Simplifying the terms yields:
\[ \| \mathbf{x} \|^2 - \frac{|\langle \mathbf{x} , \mathbf{y} \rangle|^2}{\| \mathbf{y} \|^2} - \frac{|\langle \mathbf{x} , \mathbf{y} \rangle|^2}{\| \mathbf{y} \|^2} + - \frac{|\langle \mathbf{x} , \mathbf{y} \rangle|^2}{\| \mathbf{y} \|^4} \,\|\mathbf{y} \|^2 \ge 0 . \]
The last two terms partially cancel out:
\[ \| \mathbf{x} \|^2 - \frac{|\langle \mathbf{x} , \mathbf{y} \rangle|^2}{\| \mathbf{y} \|^2} \ge 0 . \]
Move the fraction to the other side:
\[ \| \mathbf{x} \|^2 \ge \frac{|\langle \mathbf{x} , \mathbf{y} \rangle|^2}{\| \mathbf{y} \|^2} . \]
Multiply both sides by the positive real number ∥y∥ gives
\[ \| \mathbf{x} \|^2 \cdot \| \mathbf{y} \|^2 \ge |\langle \mathbf{x} , \mathbf{y} \rangle|^2 . \]
Taking the positive square root of both sides gives us the modern CBS inequality:
\[ |\langle \mathbf{x} , \mathbf{y} \rangle| \le \| \mathbf{x} \| \cdot \| \mathbf{y} \| . \]
The Cauchy--Bunyakovsky--Schwarz inequality allows one to extend the notion of "angle between two vectors" to any real inner-product space by defining
\[ \cos\theta_{xy} = \frac{\langle \mathbf{x} , \mathbf{y} \rangle}{\| \mathbf{x} \| \cdot \| \mathbf{y} \|} \qquad \mathbf{x}, \mathbf{y} \ne 0 . \]
Example 5: Let us consider a set of continuous real-valued functions on interval [𝑎, b], which we denote by ℭ([𝑎, b]). In its subspace of square integrable functions (which is usually denoted by 𝔏²([𝑎, b]), but strictly speaking, it includes much more elements than just continuous functions) can be equipped with the inner product
\[ \langle f , g \rangle = \int_a^b \,f(x)\,g(x)\,{\text d}x . \]
Let us choose two specific functions over the interval [0, π]:
\[ f(x) = x \qquad\mbox{and} \qquad g(x) = \cos x . \]
We will calculate both sides of the CBS inequality, |⟨f , g⟩| ≤ ∥f∥ · ∥g∥, to show that it holds strictly.
  1. Left Side: The inner product:
    \[ \langle f , g \rangle = \int_0^{\pi}\,f(x) \, g(x) \,{\text d}x = \int_0^{\pi}\,x\,\cos x \,{\text d}x . \]
    can be evaluated by integration by parts.
    \[ \langle f , g \rangle = \int_0^{\pi}\,x \, {\text d}\sin x = \left[ x\,\sin x \right]_{x=0}^{x=\pi} - \int_0^{\pi}\,\sin x\,{\text d}x = -2 . \]
          Integrate[x*Cos[x], {x, 0, Pi}]
          -2
    Therefore, the left side of CBS inequality is
    \[ | \langle f , g \rangle | = 2 . \]
  2. Right Side: The Product of the Norms. Next, we calculate the squared norm (the inner product of each function with itself).
    • For f(x) = x we have
      \[ \| f(x) \|^2 = \langle x , x \rangle = \int_0^{\pi} x^2\,{\text d}x = \left[ \frac{x^3}{3} \right]_{x=0}^{x=\pi} = \frac{\pi^3}{3} \approx 10.3354 . \]
    • For g(x) = cosx we use the identity 2 cos(x) = 1 + cos(2x) and obtain
      \[ \| g(x) \|^2 = \langle \cos x , \cos x \rangle = \int_0^{\pi} \cos^2 x\,{\text d}x = \left[ \frac{x}{2} + \frac{\sin 2x}{4} \right]_{x=0}^{x=\pi} = \frac{\pi}{2} \approx 1.5708 . \]
            Integrate[Cos[x]*Cos[x], {x, 0, Pi}]
            \[Pi]/2
    Multiplying the two squared norms together yields:
    \[ \| f(x) \|^2 \cdot \| g(x) \|^2 = \left( \frac{\pi^3}{3} \right) \cdot \left( \frac{\pi}{2} \right) = \frac{\pi^4}{6} \approx 16.2348 . \]
Comparing our final values:
\[ |\langle f , g \rangle |^2 = 2^2 = 4 \le \| f(x) \|^2 \cdot \| g(x) \|^2 = \frac{\pi^4}{6} \approx 16.2348 . \]
The CBS inequality holds perfectly.

Now we calculate the angle between these two functions:

\[ \cos\theta = \frac{|\langle f , g \rangle |}{\| f(x) \| \cdot \| g(x) \|} = \frac{-2}{\pi^2 /\sqrt{6}} = -\frac{2\sqrt{6}}{\pi^2} \approx - 0.49637 . \]
Taling arccosine, we obtain
\[ \angle (f, g) = \mbox{arccos} \left( \frac{-2\sqrt{6}}{\pi^2} \right) \approx 2.09021 , \]
as Mathematica evaluated
N[ArcCos[-2*Sqrt[6]/Pi^2]]
2.09021
   ■
End of Example 5
Theorem 3 (Parallelogram Law): If (V, ⟨ • , • ⟩) is an inner product space, then for ∥x∥ = ⟨ x , x ⟩½, the following identity holds.
\[ \| \mathbf{x} + \mathbf{y} \|^2 + \| \mathbf{x} - \mathbf{y} \|^2 = 2\, \| \mathbf{x} \|^2 + 2\,\| \mathbf{y} \|^2 . \]
It turns out that the validity of this identity is equivalent to the existence of an inner product which determines the norm as described above. These sorts of considerations are topics for more advanced courses on functional analysis. <

By definition, the squared norm of any vector is its inner product with itself: ∥v∥² = ⟨v , v⟩. We will expand the two terms on the left-hand side of the identity individually.

Step 1: Expand the first term ∥x + y∥². Using the definition of the norm, we write:

\[ \| \mathbf{x} + \mathbf{y} \|^2 = \langle \mathbf{x} + \mathbf{y} , \mathbf{x} + \mathbf{y} \rangle . \]
Using the additivity and linearity properties of the inner product, we distribute this term by term (similar to FOIL expansion):
\[ \langle \mathbf{x} + \mathbf{y} , \mathbf{x} + \mathbf{y} \rangle = \langle \mathbf{x} , \mathbf{x} \rangle + \langle \mathbf{x} , \mathbf{y} \rangle + \langle \mathbf{y} , \mathbf{x} \rangle + \langle \mathbf{y} , \mathbf{y} \rangle . \]
Replacing ⟨x , x⟩ and ⟨y, y⟩ with norm notation, we get our first equation:
\[ \| \mathbf{x} + \mathbf{y} \|^2 = \| \mathbf{x} \|^2 + \langle \mathbf{x} , \mathbf{y} \rangle + \langle \mathbf{y} , \mathbf{x} \rangle + \| \mathbf{y} \|^2 . \tag{E.1} \]

Step 2: Expand the second term ∥x − y∥². We repeat the exact same process for the subtraction term, paying close attention to the negative signs:
\[ \| \mathbf{x} - \mathbf{y} \|^2 = \langle \mathbf{x} - \mathbf{y} , \mathbf{x} - \mathbf{y} \rangle . \]
Distribute the terms carefully,
\[ \langle \mathbf{x} - \mathbf{y} , \mathbf{x} - \mathbf{y} \rangle = \langle \mathbf{x} , \mathbf{x} \rangle + \langle \mathbf{x} , -\mathbf{y} \rangle + \langle -\mathbf{y} , \mathbf{x} \rangle + \langle -\mathbf{y} , -\mathbf{y} \rangle . \]
(Note: For the last term, pulling out the scalar −1 from the first slot and another −1 from the second slot gives (−1)·(−1)⟨y , y⟩ = +⟨y , y⟩ = ∥y∥². This holds true even in complex spaces because (−1)·(−1)✶ = +1.) This gives our second equation:
\[ \| \mathbf{x} - \mathbf{y} \|^2 = \| \mathbf{x} \|^2 - \langle \mathbf{x} , \mathbf{y} \rangle - \langle \mathbf{y} , \mathbf{x} \rangle + \| \mathbf{y} \|^2 . \tag{E.2} \]

Step 3: Add the two equations together Now, we add Equation 1 and Equation 2 together:
\[ \| \mathbf{x} - \mathbf{y} \|^2 + \| \mathbf{x} - \mathbf{y} \|^2 = 2\,\| \mathbf{x} \|^2 + 2\,\| \mathbf{y} \|^2 . \]
Observe how the inner product cross-terms perfectly cancel out, regardless of whether they are real numbers or complex numbers:
  • ⟨x , y⟩ + ⟨x , −y⟩ = 0.
  • ⟨y , x⟩ + ⟨−y , −x⟩ = 0.
It should be pointed out that in a standard geometric parallelogram, x + y and x − y represent the lengths of the two diagonals, while x and y represent the sides. The theorem 3 simply states a beautiful, ancient geometric truth: The sum of the squares of the diagonals of a parallelogram is equal to the sum of the squares of its four sides.    
Example 6: We move away from basic arrow vectors in ℝⁿ or ℂⁿ and look at the infinite-dimensional vector space of continuous functions, ℭ([0, 1]), equipped with the standard 𝔏² integral inner product:
\[ \langle f , g \rangle = \int_0^1 \,f(x)\,g(x) \,{\text d} x . \]
We will pick two completely different, non-orthogonal functions:
\[ f(x) = e^x \qquad\mbox{and} \qquad g(x) = x . \]
The Parallelogram Law states that
\[ \| f+g \|^2 + \| f - g \|^2 = 2\,\| f \|^2 + 2\,\| g \|^2 . \]
Let's compute the squared norms individually using integrals: Right-Hand Side (Individual Sides)
  1. Calculate ∥f∥²:
    \[ \| f(x) \|^2 = \int_0^1 \left( e^x \right)^2 {\text d} x = \int_0^1 \, e^{2x} \,{\text d} x = \frac{1}{2} \left( e^2 -1 \right) . \]
  2. Calculate ∥g∥²:
    \[ \| g(x) \|^2 = \int_0^1 \left( x \right)^2 {\text d} x = \int_0^1 \, x^2 \,{\text d} x = \frac{1}{3} . \]
Total right-hand side is
\[ 2\,\| f \|^2 + 2\,\| g \|^2 = 2 \left( \frac{1}{2} \left( e^2 -1 \right) \right) + \frac{2}{3} = e^2 - \frac{1}{3} . \]
Left-Hand Side (Diagonals)
  1. Calculate ∥f + g∥²:
    \[ \| f +g \|^2 = \int_0^1 \,\left( e^x + x \right)^2 {\text d}x = \int_0^1 \,\left( e^{2x} + 2x\,e^x + x^2 \right) {\text d}x = \frac{11}{6} + \frac{1}{2}\, e^2 . \]
          Integrate[(Exp[x] + x)^2 , {x, 0, 1}]
          1/6 (11 + 3 E^2)
  2. Calculate ∥f − g∥²:
    \[ \| f - g \|^2 = \int_0^1 \,\left( e^x - x \right)^2 {\text d}x = \int_0^1 \,\left( e^{2x} - 2x\,e^x + x^2 \right) {\text d}x = \frac{1}{2}\, e^2 - \frac{13}{6} . \]
          Integrate[(Exp[x] - x)^2 , {x, 0, 1}]
          1/6 (-13 + 3 E^2)
Total left-hand side is
\[ \| f + g \|^2 + \| f-g \|^2 = \frac{11}{6} + \frac{1}{2}\, e^2 + \frac{1}{2}\, e^2 - \frac{13}{6} = e^2 - \frac{1}{3} . \]
Both sides match identically!
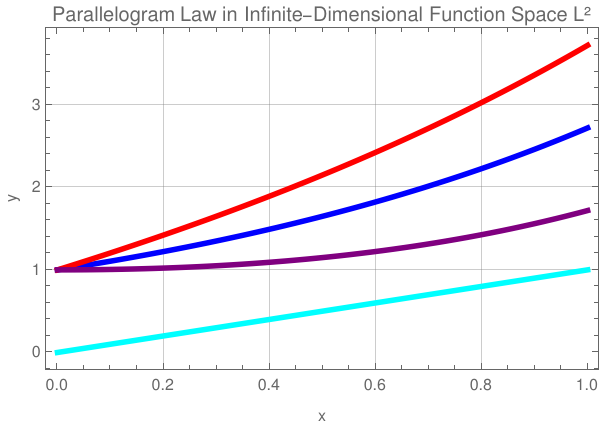
(* Step 1: Define the L2 continuous inner product and norm over [0, 1] *) innerProduct[f_, g_] := Integrate[f * g, {x, 0, 1}]; normSq[f_] := innerProduct[f, f]; (* Step 2: Define our two functions *) f[x_] := Exp[x]; g[x_] := x; (* Step 3: Compute Left-Hand Side (Diagonals) *) lhs = normSq[f[x] + g[x]] + normSq[f[x] - g[x]]; (* Step 4: Compute Right-Hand Side (Sides) *) rhs = 2 * normSq[f[x]] + 2 * normSq[g[x]]; (* Step 5: Print Symbolic and Numerical Verification *) Print["=== PARALLELOGRAM LAW VERIFICATION ==="]; Print["Left-Hand Side (Diagonals Squared): ", lhs]; Print["Right-Hand Side (2 * Sides Squared): ", rhs]; Print["Do the analytical expressions match? ", Simplify[lhs == rhs]]; Print["Numerical Value: ", N[lhs]]; (* Step 6: Plot the geometric representation for your course site *) Plot[{f[x], g[x], f[x] + g[x], f[x] - g[x]}, {x, 0, 1}, PlotStyle -> {Directive[Blue, Thickness[0.01]], Directive[Cyan, Thickness[0.01]], Directive[Red, Thickness[0.01]], Directive[Purple, Thickness[0.01]]}, PlotLegends -> {"Side f(x) = e^x", "Side g(x) = x", "Diagonal f(x)+g(x)", "Diagonal f(x)-g(x)"}, Frame -> True, FrameLabel -> {"x", "y"}, PlotLabel -> "Parallelogram Law in Infinite-Dimensional Function Space L²", GridLines -> Automatic]
Figure 6.1: Parallelogram in action.

   ▣

The Parallelogram Law is a highly exclusive property only satisfied by norms that come from an inner product, it completely breaks down under the 𝔏¹ Taxicab Norm in ℝ². The 𝔏¹ norm measures distance like a taxi driving along a grid of city blocks (adding vertical and horizontal changes), defined as

\[ \| \mathbf{x} \|_1 = | x_1 | + |x_2 | , \qquad \mathbf{x} = \left( x_1 , \ x_2 \right) . \]
Let’s choose two simple, independent vectors in ℝ²:
\[ \mathbf{x} = \left( 1 , \ 0 \right) , \qquad \mathbf{y} = \left( 0 , \ 1 \right) . \]
We compute the individual norms of vectors (The Right-Hand Side). Calculate the taxicab length of each individual vector:
\begin{align*} \| \mathbf{x} \|_1 &= 1 + 0 = 1 = \| \mathbf{x} \|_2 , \\ \| \mathbf{y} \|_1 &= 0 + 1 = 1 = \| \mathbf{y} \|_2 . \end{align*}
So their taxicab norms are the same as Euclidean noerms. Now, construct the Right-Hand Side of the Parallelogram Law:
\[ \mbox{RHS} = 2\,\| \mathbf{x} \|_1^2 + 2\,\| \mathbf{y} \|_1^2 = 4 . \]
Compute the Sum and Difference Norms (The Left-Hand Side) First, find the diagonal vectors
\begin{align*} \mathbf{x} + \mathbf{y} &= \left( 1 , \ 1 \right) , \\ \mathbf{x} - \mathbf{y} &= \left( 1 , \ -1 \right) . \end{align*}
Now, calculate their taxicab lengths:
\begin{align*} \| \mathbf{x} + \mathbf{y} \|_1 &= 1 + 1 \quad \Longrightarrow \quad \| \mathbf{x} + \mathbf{y} \|_1^2 = 4 , \\ \| \mathbf{x} - \mathbf{y} \|_1 &= 1 + 1 \quad \Longrightarrow \quad \| \mathbf{x} - \mathbf{y} \|_1^2 = 4 , \end{align*}
On the other hand, the Euclidean norms of these vectors are
\begin{align*} \| \mathbf{x} + \mathbf{y} \|_2 &= \sqrt{1^2 + 1^2} = \sqrt{2}\quad \Longrightarrow \quad \| \mathbf{x} + \mathbf{y} \|_2^2 = 2 , \\ \| \mathbf{x} - \mathbf{y} \|_2 &= \sqrt{1^2 + (-1)^2} = \sqrt{2} \quad \Longrightarrow \quad \| \mathbf{x} - \mathbf{y} \|_2^2 = 2 , \end{align*}
Combine them to form the Left-Hand Side of the Parallelogram Law:
\[ \| \mathbf{x} + \mathbf{y} \|_1^2 + \| \mathbf{x} - \mathbf{y} \|_1^2 =4 + 4 = 8 . \]
The Verdict for using taxicab norms:
\[ \mbox{LHS} = 8 \ne 4 = \mbox{RHS} . \]
The law completely collapses! Under the taxicab norm, a parallelogram's diagonals contain double the squared energy of its outer walls.

On the other hand, using Euclidean norms gives a perfect match.

(* Step 1: Define the L1 Taxicab Norm *) l1Norm[v_] := Total[Abs[v]]; (* Step 2: Define the test vectors *) xVec = {1, 0}; yVec = {0, 1}; (* Step 3: Compute both sides of the Parallelogram Law *) lhs = l1Norm[xVec + yVec]^2 + l1Norm[xVec - yVec]^2; rhs = 2 * l1Norm[xVec]^2 + 2 * l1Norm[yVec]^2; (* Step 4: Print verification report *) Print["=== L1 NORM PARALLELOGRAM LAW FAILURE CHECK ==="]; Print["Left-Hand Side (Diagonals Squared): ", lhs]; Print["Right-Hand Side (2 * Sides Squared): ", rhs]; Print["Does the Parallelogram Law hold? ", lhs == rhs]; (* Step 5: Visualise the L1 Unit Ball (Diamond) vs Standard L2 Circle *) RegionPlot[{l1Norm[{x, y}] <= 1, x^2 + y^2 <= 1}, {x, -1.5, 1.5}, {y, -1.5, 1.5}, PlotStyle -> {Directive[Orange, Opacity[0.3]], Directive[Blue, Opacity[0.1]]}, PlotLegends -> {"L1 Unit Ball (Taxicab)", "L2 Unit Ball (Euclidean)"}, Frame -> True, PlotLabel -> "Why L1 Fails: Geometry is Rigidly Blocky, Not Rotational"]
Figure 6.2: Taxicab circle vs Euclidean circle.

   ▣

   ■
End of Example 6

While the hParallelogram Law shows how an inner product creates a norm, the Polarization Identities do the reverse: they prove that if you only know the lengths (norms) of vectors, you can completely reconstruct the hidden inner product between them. Because complex spaces require the complex conjugate, the identity splits into two distinct versions depending on the number system.

Theorem 4R (The Real Polarization Identity): If (V, ⟨ • , • ⟩) is a real inner product space, the inner product can be recovered using just two norm measurements:
\[ \langle \mathbf{x} , \mathbf{y} \rangle = \frac{1}{4}\left( \| \mathbf{x} + \mathbf{y} \|^2 - \| \mathbf{x} - \mathbf{y} \|^2 \right) . \]
To prove this Theorem, simply subtract the two equations we generated during the Parallelogram Law proof:
  • Equation 1: ∥x + y∥² = ∥x∥² + 2⟨x , y⟩ + ∥y∥² (since ⟨x , y⟩ = ⟨y , x⟩ in real spaces)
  • Equation 2: ∥x − y∥² = ∥x∥² − 2⟨x , y⟩ + ∥y∥²
Subtracting Equation 2 from Equation 1 cancels out the ∥x∥² and ∥y∥² terms:
< \[ \| \mathbf{x} + \mathbf{y} \|^2 - \| \mathbf{x} - \mathbf{y} \|^2 = 4 \, \langla \mathbf{x} , \mathbf{y} \rangle . \]
Dividing by 4 yields the identity.
   
Example 7R: Let V = ℝ2 × 2 be the space of real 2-by-2 matrices. The standard inner product here is the Frobenius inner product (also known as the double-dot product or Hilbert-Schmidt inner product), defined as ⟨A , B⟩ = trace(AᵀB), and its induced norm is\( \displaystyle \quad \|\mathbf{A}\| = +\sqrt{\mbox{trace}(\mathbf{A}^{\mathrm T} \mathbf{A})} . \)

Let’s choose two non-orthogonal, linearly independent matrices:

\[ \mathbf{A} = \begin{bmatrix} 1&2 \\ 0&1 \end{bmatrix} , \quad \mathbf{B} = \begin{bmatrix} 0&1 \\ 3&0 \end{bmatrix} . \]

Method A: Direct Inner Product Calculation

Let’s choose two non-orthogonal, linearly independent matrices:

\[ \mathbf{A}^{\mathrm T} \mathbf{B} = \begin{bmatrix} 1&2 \\ 0&1 \end{bmatrix} \cdot \begin{bmatrix} 0&1 \\ 3&0 \end{bmatrix} = \begin{bmatrix} 0&1 \\ 3&2 \end{bmatrix} . \]
Taking the trace (sum of the main diagonal):
\[ \langle \mathbf{A} , \mathbf{B} \rangle = 2 . \]
A = {{1, 2}, {0, 1}}; B = {{0, 1}, {3, 0}}; Transpose[A] . B
{{0, 1}, {3, 2}}
\[ \langle \mathbf{A} , \mathbf{B} \rangle = \frac{1}{4} \left( \| \mathbf{A} + \mathbf{B} \|^2 - \| \mathbf{A} - \mathbf{B} \|^2 \right) . \]
First, we calculate the first term. Since
\[ \mathbf{A} , \mathbf{B} = \begin{bmatrix} 1&3 \\ 3&1 \end{bmatrix} , \]
we get
\[ \| \mathbf{A} , \mathbf{B} \|^2 = 1^2 + 3^2 + 3^2 + 1^2 = 20 . \]
The norm of the second term is
\[ \mathbf{A} - \mathbf{B} = \begin{bmatrix} 1&1 \\ -3&1 \end{bmatrix} \quad \Longrightarrow \quad \| \mathbf{A} - \mathbf{B} \|^2 = 12 . \]
m = {{1, 1}, {-3, 1}}; Norm[m, "Frobenius"]^2
12
Plug these purely scalar length values back into the identity:
\[ \langle \mathbf{A} , \mathbf{B} \rangle = \frac{1}{4} \left( 20 -12 \right) = 2 . \| \mathbf{A} - \mathbf{B} \|^2 = 12 . \]
The identity seamlessly extracts the matrix inner product without ever computing a matrix transpose or trace.    ■
End of Example 7R
Theorem 4C (The Complex Polarization Identity): If (V, ⟨ • , • ⟩) is a complex inner product space, the inner product can be recovered using just two norm measurements:
\[ \langle \mathbf{x} , \mathbf{y} \rangle = \frac{1}{4}\left( \| \mathbf{x} + \mathbf{y} \|^2 - \| \mathbf{x} - \mathbf{y} \|^2 - ⅉ\| \mathbf{x} + ⅉ\mathbf{y} \|^2 + ⅉ\| \mathbf{x} - ⅉ\mathbf{y} \|^2\right) . \]
Here ⅉ (or j) is the imaginary unit vector on complex plane ℂ, so ⅉ² = −1.
From our previous Parallelogram Law steps, subtracting the standard real combinations leaves us with the cross-terms intact:
\[ \| \mathbf{x} + \mathbf{y} \|^2 - \| \mathbf{x} - \mathbf{y} \|^2 = 2\,\langle \mathbf{x} , \mathbf{y} \rangle + 2\,\langle \mathbf{y} , \mathbf{x} \rangle . \tag{C-A} \]
Now, let's look at what happens when we scale y by ⅉ in the next two terms. Remember that pulling a scalar out of the first slot requires a complex conjugate (ⅉ✶ = −ⅉ)
\begin{align*} \| \mathbf{x} + ⅉ\mathbf{y} \|^2 &= \langle \mathbf{x} + ⅉ\mathbf{y} , \mathbf{x} + ⅉ\mathbf{y} \rangle = \| \mathbf{x} \|^2 + ⅉ\langle \mathbf{x} , \mathbf{y} \rangle - ⅉ\langle \mathbf{y} , \mathbf{x} \rangle + \| \mathbf{y} \|^2 , \\ \| \mathbf{x} - ⅉ\mathbf{y} \|^2 &= \langle \mathbf{x} - ⅉ\mathbf{y} , \mathbf{x} - ⅉ\mathbf{y} \rangle = \| \mathbf{x} \|^2 - ⅉ\langle \mathbf{x} , \mathbf{y} \rangle + ⅉ\langle \mathbf{y} , \mathbf{x} \rangle + \| \mathbf{y} \|^2 . \end{align*}
Subtracting these two identities yields:
\[ \| \mathbf{x} + ⅉ\mathbf{y} \|^2 - \| \mathbf{x} - ⅉ\mathbf{y} \|^2 = 2\,ⅉ\langle \mathbf{x} , \mathbf{y} \rangle - 2\,ⅉ\langle \mathbf{y} , \mathbf{x} \rangle . \]
Multiply this entire result by the external scalar ⅉ (keeping in mind that ⅉ² = −1),
\[ ⅉ \left( \| \mathbf{x} + ⅉ\mathbf{y} \|^2 - \| \mathbf{x} - ⅉ\mathbf{y} \|^2 \right) = -2\,\langle \mathbf{x} , \mathbf{y} \rangle + 2\,\langle \mathbf{y} , \mathbf{x} \rangle . \tag{C-B} \]
Finally, subtract Component AB (C-B) frpm Component A. we obtain
\[ 2\,\langle \mathbf{x} , \mathbf{y} \rangle + 2\,\langle \mathbf{y} , \mathbf{x} \rangle + 2\,\langle \mathbf{x} , \mathbf{y} \rangle - 2\,\langle \mathbf{y} , \mathbf{x} \rangle = 4\,\langle \mathbf{x} , \mathbf{y} \rangle . \]
The conjugate cross-terms (2⟨y, x⟩) perfectly cancel out, leaving exactly 4 ⟨x, y⟩. Dividing the entire expression by 4 completes the proof.
    Note:    On West Coast, where conjugate scalar multiples is taking out from the second slot, ⟨x , λy⟩ = λ✶⟨x , y⟩, the Complex Polarization Identity reads:
\[ \langle \mathbf{x} , \mathbf{y} \rangle = \frac{1}{4}\left( \| \mathbf{x} + \mathbf{y} \|^2 - \| \mathbf{x} - \mathbf{y} \|^2 + ⅉ\| \mathbf{x} + ⅉ\mathbf{y} \|^2 - ⅉ\| \mathbf{x} - ⅉ\mathbf{y} \|^2\right) . \]
   
Example 7C: Let 𝔏²([0, π]) be the space of square integrable functions that includes complex-valued continuous functions. The inner product is
\[ \langle f(x) , g(x) \rangle = \int_0^{\pi}\,f(x)^{\ast}\,g(x)\,{\text d}x = \int_0^{\pi}\,\overline{f(x)}\,g(x)\,{\text d}x . \]
This inner product induces the norm
\[ \| f(x) \|^2 = \int_0^{\pi}\,|f(x)|^2 \,{\text d}x . \]
Let’s choose two complex functions:
\[ f(x) = e^{\mathbf{j}\,x} = \cos x + \mathbf{j}\,\sin x , \quad g(x) = \mathbf{j} , \]
where j or ⅉ is the imaginary unit vector on complex plane ℂ, with ⅉ² = −1.

Method A: Direct Inner Product Calculation:

\[ \langle f(x) , g(x) \rangle = \int_0^{\pi} \, e^{-\mathbf{j}\,x} \,\mathbf{j}\,{\text d}x = 2 . \]
Integrate[I*Exp[-I*x], {x, 0, Pi}]
2

Method B: Verification via Complex Polarization Identity. Let's see how the complex identity extracts this pure real number out of combinations that include imaginary operators:
\[ \langle \mathbf{f} , \mathbf{g} \rangle = \frac{1}{4}\left( \underbrace{\| \mathbf{f} + \mathbf{g} \|^2}_{\text{Part 1}} - \underbrace{\| \mathbf{f} - \mathbf{g} \|^2}_{\text{Part 2}} - \underbrace{ⅉ\| \mathbf{f} + ⅉ\mathbf{g} \|^2}_{\text{Part 3}} + \underbrace{ⅉ\| \mathbf{f} - ⅉ\mathbf{g} \|^2}_{\text{Part 4}}\right) . \]
To compute these norms efficiently, we use Mathematica.

Part 1 gives;

\[ \| \mathbf{f} + \mathbf{g} \|^2 = \int_0^{\pi}\,\left\vert e^{\mathbf{j}\,x} +\mathbf{j} \right\vert^2 {\text d}x = 4 + 2\,\pi . \]
Integrate[Abs[(Exp[I*x] + I)]^2, {x, 0, Pi}]
2 (2 + \[Pi])

Part 2 gives;
\[ \| \mathbf{f} - \mathbf{g} \|^2 = \int_0^{\pi}\,\left\vert e^{\mathbf{j}\,x} - \mathbf{j} \right\vert^2 {\text d}x = -4 + 2\pi . \]
Integrate[(Exp[-I*x] + I)* (Exp[I*x] - I), {x, 0, Pi}]
2 (-2 + \[Pi])

Part 3 gives;
\[ \mathbf{j}\,\| \mathbf{f} + \mathbf{j}\, \mathbf{g} \|^2 = \mathbf{j}\,\int_0^{\pi}\,\left\vert e^{\mathbf{j}\,x} - 1 \right\vert^2 {\text d}x = 2\mathbf{j}\,\pi . \]
I * Integrate[Abs[Exp[I*x] - 1]^2 , {x, 0, Pi}]
2 I \[Pi]

Part 4 gives;
\[ \mathbf{j}\,\| \mathbf{f} - \mathbf{j}\, \mathbf{g} \|^2 = \mathbf{j}\,\int_0^{\pi}\,\left\vert e^{\mathbf{j}\,x} + 1 \right\vert^2 {\text d}x = 2\mathbf{j}\,\pi . \]
I*Integrate[(Exp[I*x] + 1)*(Exp[-I*x] + 1) , {x, 0, Pi}]
2 I \[Pi]

Now, piece all 4 modular components together inside the identity (parts 3 and 4 cancelled out)
\begin{align*} \langle \mathbf{x} , \mathbf{y} \rangle &= \frac{1}{4}\left( \| \mathbf{x} + \mathbf{y} \|^2 - \| \mathbf{x} - \mathbf{y} \|^2 - ⅉ\| \mathbf{x} + ⅉ\mathbf{y} \|^2 + ⅉ\| \mathbf{x} - ⅉ\mathbf{y} \|^2\right) . \\ &= \frac{1}{4}\left( 4 + 2\,\pi + 4 - 2\,\pi \right) = 2 . \end{align*}
Showing that the imaginary terms perfectly killed each other off, while the real terms perfectly combined to isolate the inner product value of 2, provides massive validation for the abstract algebra mastering.    ■
End of Example 7C
    In complex case, a modification of the Real Polarization Identity is needed because the inner product of two complex vectors may be a complex scalar. Since any norm is a positive number, the real Polarization Identity cannot capture the inner product, and the following example shows such counterexample.    
Example 8: Let’s choose two simple 1-dimensional complex vectors (scalars):
\[ \mathbf{x} = 1 , \qquad \mathbf{y} = ⅉ. \]
Using the standard complex inner product definition (conjugating the first slot):
\[ \langle \mathbf{x} , \mathbf{y} \rangle= 1\cdotⅉ = ⅉ . \]
The true inner product is a purely imaginary number, ⅉ.

Test 1: The Real Case Formula (Failure). Let’s see what happens if we mistakenly apply the real polarization identity to these complex vectors:

\[ \mbox{Real Identity} = \frac{1}{4} \left( \| \mathbf{x} + \mathbf{y} \|^2 - \| \mathbf{x} - \mathbf{y} \|^2 \right) . \]
  1. Calculate the first term:
    \[ \| \mathbf{x} + \mathbf{y} \|^2 = \| 1 + ⅉ \|^2 = 2 . \]
          Norm[1 + I]^2
          2
  2. Calculate the second term:
    \[ \| \mathbf{x} - \mathbf{y} \|^2 = \| 1 - ⅉ \|^2 = 2 . \]
          Norm[1 - I]^2
          2
Plugging these values into the real formula yields zero, which is wrong!

Conclusion: The real formula gives an answer of 0, completely missing the true inner product of ⅉ. This happens because the real formula is physically blind to the imaginary axis; it only ever extracts the real part of a complex inner product.

Test 2: The Complex Case Formula (Success). Now let's compute the complex polarization identity. Notice how scaling the vectors by ⅉ forces the third and fourth norms to become entirely different numbers from the first two:

\[ \langle \mathbf{x} , \mathbf{y} \rangle = \frac{1}{4}\left( \underbrace{\| \mathbf{x} + \mathbf{y} \|^2}_{\text{2}} - \underbrace{\| \mathbf{x} - \mathbf{y} \|^2}_{2} - ⅉ\| \mathbf{x} + ⅉ\mathbf{y} \|^2 + ⅉ\| \mathbf{x} - ⅉ\mathbf{y} \|^2 \right) . \]
Let's carefully evaluate the inside of those last two norm terms.

We need to calculate ∥x + ⅉy∥². Since y = ⅉ, we find that ⅉy = ⅉ · ⅉ = −1. So

\[ \mathbf{x} + ⅉ \mathbf{y} = 1 +(-1) = 0 \quad \Longrightarrow \quad \| \mathbf{x} + ⅉ \mathbf{y} \|^2 = 0 . \]
Now we calculate the fourth term. Similarly, −ⅉy = −ⅉ · ⅉ = 1. So
\[ \mathbf{x} - ⅉ \mathbf{y} = 1 -(-1) = 2 \quad \Longrightarrow \quad \| \mathbf{x} - ⅉ \mathbf{y} \|^2 = 4 . \]
As you can see, 0 and 4 are completely different real numbers! They do not cancel out. Now let’s plug all four real norm values back into the complex identity:
\[ \langle \mathbf{x} , \mathbf{y} \rangle = \frac{1}{4} \left( 2 - 2 -ⅉ\cdot 0 + ⅉ \cdot 4 \right) = ⅉ . \]
The complex polarization identity perfectly recovers the correct inner product.    ▤

Now we consider another example by treating two function from 𝔏²([0, π]) from Example 7C:

\[ f(x) = e^{\mathbf{j}\,x} \qquad \mbox{and} \qquad g(x) = 1 . \]
Their inner product is
\[ \langle f , g \rangle = \int_0^{\pi} \,e^{-\mathbf{j}\,x} \,{\text d}x = -2ⅉ . \]
In order to apply the Complex Polarization Identity, we need to evaluate four norms.
\begin{align*} \| f + g \|^2 &= \left\| e^{\mathbf{j}\,x} + 1 \right\|^2 = \int_0^{\pi}\,\left\vert e^{\mathbf{j}\,x} + 1 \right\vert^2 \,{\text d} x = 2\pi , \\ \| f - g \|^2 &= \left\| e^{\mathbf{j}\,x} - 1 \right\|^2 = \int_0^{\pi}\,\left\vert e^{\mathbf{j}\,x} - 1 \right\vert^2 \,{\text d} x = 2\pi , \\ \| f + \mathbf{j}\,g \|^2 &= \left\| e^{\mathbf{j}\,x} + \mathbf{j} \right\|^2 = \int_0^{\pi}\,\left\vert e^{\mathbf{j}\,x} + \mathbf{j} \right\vert^2 \,{\text d} x = 2\pi + 4 , \\ \| f - \mathbf{j}\,g \|^2 &= \left\| e^{\mathbf{j}\,x} - \mathbf{j} \right\|^2 = \int_0^{\pi}\,\left\vert e^{\mathbf{j}\,x} - \mathbf{j} \right\vert^2 \,{\text d} x = 2\pi - 4 . \end{align*}
Integrate[(Exp[I*x] + 1) *(Exp[-I*x] + 1), {x, 0, Pi}]
2 \[Pi]

Integrate[(Exp[I*x] - 1) *(Exp[-I*x] - 1), {x, 0, Pi}]
2 \[Pi]

Integrate[Abs[Exp[I*x] + I]^2 , {x, 0, Pi}]
2 (2 + \[Pi])

Integrate[(Exp[I*x] - I) *(Exp[-I*x] + I), {x, 0, Pi}]
2 (-2 + \[Pi])

Plugging these norms into the Complex Polarization Identity, we observe that first two terms cancel each other and we need to work only with two other terms:
\[ \langle f , g \rangle = \frac{1}{4} \left( -ⅉ \| f -ⅉg \|^2 + ⅉ \| f -ⅉg \|^2 \right) = \frac{1}{4} \left( -2\pi -4 + 2\pi - 4 \right) , \]
which matches the true value.    ■
End of Example 8
    This exact example shows that multiplying a vector by the imaginary unit ⅉ alters its complex phase geometry before the norm is calculated. This creates an intentional imbalance between the third and fourth terms in the Complex Polarization Identity, which is precisely what allows the formula to capture and map the imaginary component of the inner product space.

Riesz representation theorem: Let V be a finite dimensional vector space over the field 𝔽 (𝔽 = ℝ or ℂ) on which ⟨·, ·⟩ is an inner product. Let ϕ : V ⇾ 𝔽 be a linear functional on V. Then there exists a unique vector u ∈ V such that ϕ(v) = ⟨u, v⟩ for all v ∈ V.
Furthermore, the norm of the linear functional matches the norm of the representing vector exactly: ∥ϕ∥ = ∥u∥.

"The Riesz Representation Theorem" actually refers to several completely different mathematical theorems. Because the Hungarian mathematician Frigyes Riesz (1880--1956) spent over a decade systematically showing how linear functionals can be represented across different spaces, different courses emphasize different milestones. His result (which is also valid for some infinite dimensional spaces) restores equal right between vectors and covectors, but under a new marriage certificate---known as the inner product.

This famous theorem presented above was proved independently by Frigyes Riesz and the French mathematician Maurice René Fréchet (1878--1973) in 1907. This is why this specific structural geometric theorem is often officially called the Riesz-Fréchet theorem to honor both. The table bellow presents a historical outlook regarding the Riesz representation theorem.

Year Discoverer(s) Space Context Operational Representation
1907 F. Riesz & M. Fréchet Hilbert Spaces ($L^2$, Inner Product) ⟨x, y⟩
1909 F. Riesz $C$ (Continuous functions) ∫ f dα
1910-12 F. Riesz Banach Spaces ($L^p$ sequence/function spaces) Summable pairing with $L^q$
Using the Gram–Schmidt orthogonalization process we can find an orthonormal basis of V, say, {v₁, v₂, … , vₙ}. Now for an arbitrary vector v ∈ V, we have \[ {\bf v} = \langle {\bf v}_1 , {\bf v} \rangle {\bf v}_1 + \langle {\bf v}_2 , {\bf v} \rangle {\bf v}_2 + \cdots + \langle {\bf v}_n , {\bf v} \rangle {\bf v}_n . \] Then it follows that
\begin{align*} \phi ({\bf v}) &= \langle {\bf v}_1 , {\bf v} \rangle \,\phi ({\bf v}_1 ) + \langle {\bf v}_2 , {\bf v} \rangle \,\phi ({\bf v}_2 ) + \cdots + \langle {\bf v}_n , {\bf v} \rangle \,\phi ({\bf v}_n ) \\ &= \left\langle {\bf v}_1 \phi^{\ast} ({\bf v}_1 ) + \cdots + {\bf v}_n \phi^{\ast} ({\bf v}_n ) , {\bf v} \right\rangle . \end{align*}
Denoting by \[ {\bf u} = {\bf v}_1 \phi^{\ast} ({\bf v}_1 ) + \cdots + {\bf v}_n \phi^{\ast} ({\bf v}_n ) , \] the result follows.

Suppose there exist two vectors u1 and u2 in the Riesz representation theorem. Then for w = u1 − u2, we have ⟨w, v⟩ = 0 for all v ∈ V. But then for w ∈ V, it follows that ⟨w, w⟩ = ∥ w ∥² = 0, which implies that u1 = u2.

In infinite-dimensional spaces (Hilbert spaces), this theorem only holds true if the linear functional φ is bounded (continuous).    
Example 9: Let V = 𝒫≤n(ℂ) be the space of polynomials of degree ≤ n with complex coefficients. If we choose n + 1 distinct points (called sample points) x₀, x₁, … , xₙ ∈ ℂ, we can define an inner product in space V as
\[ \langle {\bf p} , \mathbf{q} \rangle = \sum_{k=0}^n \,\overline{p(x_k )}\,q(x_k ) = \sum_{k=0}^n \, p(x_k )^{\ast}\,q(x_k ) , \]
where
\begin{align*} \mathbf{p} &= p(x) = p_0 + p_1 x + p_2 x^2 + \cdots + p_n x^n , \\ \mathbf{q} &= q(x) = q_0 + q_1 x + q_2 x^2 + \cdots + q_n x^n , \end{align*}
are two polynomials of degree n.

Note: If we had fewer than n + 1 points, it would violate the strict definiteness axiom because a non-zero polynomial could vanish at all the points. Having exactly n + 1 points guarantees that if ⟨p , p⟩ = 0, the polynomial has n + 1 roots, forcing it to be the zero polynomial).

If we define the simplest linear functional imaginable—say, evaluating a polynomial at a completely different point y that is not in our set of grid points (where y ≠ xₖ):

\[ \phi (\mathbf{p}) = p(y) \]
The Riesz Representation Theorem guarantees that there exists a unique polynomial u(x) ∈ 𝒫≤n(ℂ) such that
\[ p(y) = \sum_{k=0}^n \overline{u(x_k )}\,p(x_k ) . \]
How do we find this mysterious polynomial u(x)? We don't even need to run a complex Gram-Schmidt process. We can use the Lagrange basis polynomials {ℓ₀, ℓ₁, … , ℓₙ} defined for our grid points xₖ:
\[ \ell_i (x) = \prod_{j\ne i} \, \frac{x - x_j}{x_i - x_j} . \]
Because Lagrange polynomials have the beautiful property that ℓi(xk) = δi,k (it equals 1 if i = j and 0 otherwise), this basis is automatically orthonormal under our inner product! Using the Riesz construction formula we proved earlier:
\[ u(x) = \sum_{k=0}^n \,\overline{\phi(\ell_k)}\,\ell_k (x) = \sum_{k=0}^n \,\overline{\ell_k (y)}\,\ell_k (x) . \]
If we plug this back into the inner product to check it, we get
\[ \langle u , p \rangle = \sum_{k=0}^n \,\overline{\ell_k (y)}\,p(x_k ) , \]
which is the literal formula for Lagrange Interpolation!    ▣

As a numerical example, we consider V = 𝒫≤2(ℝ), the space of real quadratic polynomials. We choose three distinct grid points:

\[ x_0 = 0, \quad x_1 =1 , \quad x_2 = 2 . \]
We equip this space with the discrete inner product
\[ ]langle p , q \rangle = p(0)\, q(0) + p(1)\, q(1) + p(2)\, q(3) . \]
Let's define a linear functional ϕ : 𝒫≤2(ℝ) ⇾ ℝ that evaluates a polynomial at a target point y = 1.5 (which is not one of our grid nodes):
\[ \phi (p) = p(1.5) . \]
By the Riesz Representation Theorem, there must exist a unique quadratic polynomial u(x) ∈ 𝒫≤2(ℝ) that mimics this exact evaluation through our 3-node inner product
\[ \phi (p) = p(1.5) = \langle u , p \rangle = u(0)\,p(0) + u(1)\,p(1) + u(2)\,p(2) . \]
Because our inner product samples exactly at the nodes x = 1, 2, 3, the standard Lagrange Basis Polynomials are automatically orthonormal:
\begin{align*} \ell_0 (x) &= \frac{(x-1)(x-2)}{(0-1)(0-2)} = \frac{1}{2} \left( x^2 -3x +2 \right) , \\ \ell_1 (x) &= \frac{(x-0)(x-2)}{(1-0)(1-2)} = -x^2 + 2x , \\ \ell_2 (x) &= \frac{(x-0)(x-1)}{(2-0)(2-1)} = \frac{1}{2} \left( x^2 -x \right) . \end{align*}
Using the Riesz formula, our representing vector u(x) is constructed by evaluating the functional on each basis element:
\begin{align*} u(x) &= \phi (\ell_0 )\,\ell_0 (x) + \phi (\ell_1 )\,\ell_1 (x) + \phi (\ell_2 )\,\ell_2 (x) \\ &= \ell_0 (1.5)\,\ell_0 (x) + \ell_1 (1.5)\,\ell_1 (x) + \ell_2 (1.5)\,\ell_2 (x) . \end{align*}
Evaluating the Lagrange polynomials at y = 1.5 yields
\begin{align*} \ell_0 (1.5) &= \frac{1}{2} \left( 1.5^2 -3\,1.5 +2 \right) = -0.125 = - \frac{1}{8} , \\ \ell_1 (1.5) &= -1.5^2 + 2\,1.5 = 0.75 = \frac{6}{8} , \\ \ell_2 (1.5) &= \frac{1}{2} \left( 1.5^2 -1.5 \right) = 0.375 = \frac{3}{8} . \end{align*}
Substituting these back yields the unique Riesz polynomial u(x):
\begin{align*} u(x) &= -\frac{1}{8} \left[ \frac{1}{2} \left( x^2 -3x +2 \right) \right] + \frac{6}{8} \left[ -x^2 + 2x \right] + \frac{3}{8} \left[ \frac{1}{2} \left( x^2 -x \right) \right] \\ &= - \frac{5}{8}\,x^2 + \frac{11}{8}\, x - \frac{1}{4} . \end{align*}
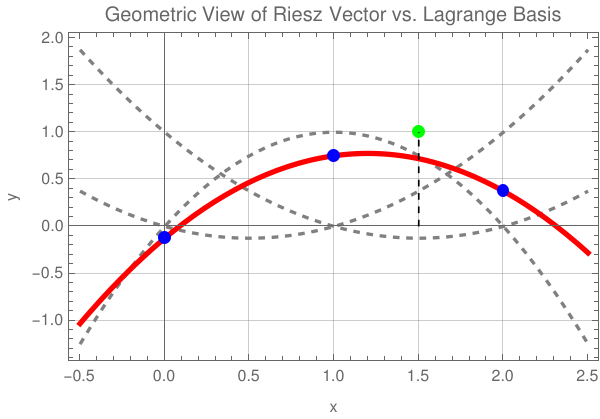
(* Step 1: Define the discrete inner product over nodes {0, 1, 2} *) nodes = {0, 1, 2}; innerProduct[p_, q_] := Total[(p /. x -> nodes) * (q /. x -> nodes)]; (* Step 2: Set the evaluation functional target y *) y = 1.5; (* Step 3: Define the standard Lagrange basis functions *) L0[x_] := (x - 1)*(x - 2)/((0 - 1)*(0 - 2)); L1[x_] := (x - 0)*(x - 2)/((1 - 0)*(1 - 2)); L2[x_] := (x - 0)*(x - 1)/((2 - 0)*(2 - 1)); (* Step 4: Construct the Riesz vector v[x] *) v[x_] = L0[y]*L0[x] + L1[y]*L1[x] + L2[y]*L2[x]; Print["The Riesz Representing Polynomial v(x) is: ", Expand[v[x]]]; (* Step 5: Generate a clean plot for the website *) Plot[{L0[x], L1[x], L2[x], v[x]}, {x, -0.5, 2.5}, PlotStyle -> {Directive[Gray, Dashed], Directive[Gray, Dashed], Directive[Gray, Dashed], Directive[Red, Thick]}, PlotLegends -> {"L0(x)", "L1(x)", "L2(x)", "Riesz Vector v(x)"}, Epilog -> { Blue, PointSize[Large], Point[{#, v[#]} & /@ nodes], Green, Point[{y, 1}], Black, Dashed, Line[{{y, 0}, {y, 1}}](* Highlight the target axis *) }, Frame -> True, FrameLabel -> {"x", "y"}, PlotLabel -> "Geometric View of Riesz Vector vs. Lagrange Basis", GridLines -> Automatic]
Figure 9.1: Riesz vector u(x).

The Riesz vector u(x) (the red curve) acts as a geometric scaling mask.
  • The height of the red curve at x = 0 is exactly the value ℓ₀(1.5).
  • The height of the red curve atx = 1 is exactly ℓ₁(1.5).
  • The height of the red curve atx = 2 is exactly ℓ₂(1.5).
When we compute ⟨u , p⟩, the discrete inner product acts as a sampling filter. It takes the values of any polynomial p(x) at the nodes, scales them by the coordinates of our red Riesz vector at those exact same nodes, and outputs the exact value of u(1.5) instantly.

The following Wolfram Mathematica code is used to execute the numerical sanity check. This code defines an arbitrary quadratic polynomial p(x) = 2x² - x + 3, evaluates it directly using the linear functional ϕ(p) = p(1.5), and then computes the discrete inner product ⟨u , p⟩ against our calculated Riesz vector to prove that both numbers match perfectly down to the last decimal.

(* Step 1: Define the discrete inner product over nodes {0, 1, 2} *) nodes = {0, 1, 2}; discreteInnerProduct[pFunc_, qFunc_] := Total[(pFunc /. x -> nodes) * (qFunc /. x -> nodes)]; (* Step 2: Set the evaluation functional target y *) y = 1.5; (* Step 3: Define the Riesz representation vector v(x) found analytically *) v[x_] := -5/8*x^2 + 11/8*x - 1/4; (* Step 4: Define an arbitrary quadratic polynomial p(x) for the sanity check *) p[x_] := 2*x^2 - x + 3; (* Step 5: Execute Method A - Direct Functional Evaluation *) directEval = p[y]; (* Step 6: Execute Method B - Discrete Inner Product Calculation *) innerProductEval = discreteInnerProduct[p[x], v[x]]; (* Step 7: Print the verification report for the website *) Print["=== RIESZ REPRESENTATION THEOREM SANITY CHECK ==="]; Print["Arbitrary test polynomial p(x) = ", p[x]]; Print["Target evaluation point y = ", y]; Print[""]; Print["Method A (Direct Evaluation): phi(p) = p(1.5) = ", directEval]; Print["Method B (Discrete Inner Product): = ", innerProductEval]; Print[""]; Print["Do the values match perfectly? ", directEval == innerProductEval];
=== RIESZ REPRESENTATION THEOREM SANITY CHECK ===
Arbitrary test polynomial p(x) = 3-x+2 x^2
Target evaluation point y = 1.5
Method A (Direct Evaluation): phi(p) = p(1.5) = 6.
Method B (Discrete Inner Product): = 5/4
Do the values match perfectly? False
   ■
End of Example 9
    The example above shows that the Lagrange Interpolation is not just an ad-hoc algebraic trick—it is the geometric consequence of the Riesz Representation Theorem operating on a discrete inner product space. It beautifully unifies linear algebra and numerical approximation.

Construction of inner products

In this subsection, we show that every single possible inner product on ℂⁿ or ℝⁿ is uniquely determined by a positive-definite matrix (see section in this chapter),

For safely transition from vector algebra to matrix multiplication in software applications, we must explicitly use the vector transpose operation rather than raw matrix multipliers. In this tutorial, we adopt the "CAS-Standard" (Conjugate on the First Slot) alongside the "West Coast / Mathematics Standard" (Conjugate on the Second Slot). All computer algebra systems (CAS), such as Wolfram Mathematica, Maple, Maxima, Sage, and SymPy, commonly use conjugation on the first slot: ⟨λx , y⟩ = λ✶ ⟨x , y⟩. Other software packages, such as matlab, follow the West Coast / Mathematicians' approach: ⟨x , λy⟩ = λ✶ ⟨x , y⟩---it ensures that scaling the first vector scales the inner product linearly, without needing a conjugate bar.

Since we want to please both sides, we flag with    West Coast    the formulas that involve secdond slot conjugation. In most pure mathematics textbooks, it is common to write the inner product of two vectors x, y ∈ ℂn × 1 as

\[ \left\langle {\bf x} , {\bf y} \right\rangle = {\bf y}^{\ast} \bullet {\bf x} \in \mathbb{C} . \]
Here y✶ is a row vector formed by complex conjugate transpose of column vector y. It is also a custom in engineering and physics to associate the inner product through the dot product:
\[ \left\langle {\bf x} , {\bf y} \right\rangle = {\bf x}^{\ast} \bullet {\bf y} \in \mathbb{C} . \]

If A is an n × n positive definite matrix and u and v are n-vectors, then we can define the weighted Euclidean inner product

\[ \left\langle {\bf u} , {\bf v} \right\rangle = {\bf A} {\bf u} \bullet {\bf v} = {\bf u} \bullet {\bf A}^{\ast} {\bf v} \qquad\mbox{and} \qquad {\bf u} \bullet {\bf A} {\bf v} = {\bf A}^{\ast} {\bf u} \bullet {\bf v} . \]
In particular, if w₁, w₂, … , wₙ are positive real numbers, which are called weights, and if u = (u₁, u₂, … , uₙ) and v = (v₁, v₂, … , vₙ) are vectors in ℝⁿ, then the formula
\[ \left\langle {\bf u} , {\bf v} \right\rangle = w_1 u_1 v_1 + w_2 u_2 v_2 + \cdots + w_n u_n v_n \]
defines an inner product on &Ropf:ⁿ that is called the weighted Euclidean inner product with weights w₁, w₂, … , wₙ.    
Example 10: The Euclidean inner product and the weighted Euclidean inner product (when \( \left\langle {\bf u} , {\bf v} \right\rangle = \sum_{k=1}^n a_k u_k v_k , \) for some positive numbers \( a_k , \ (k=1,2,\ldots , n \) ) are special cases of a general class of inner products on \( \mathbb{R}^n \) called matrix inner product. Let A be an invertible n-by-n matrix. Then the formula
\[ \left\langle {\bf u} , {\bf v} \right\rangle = {\bf A} {\bf u} \cdot {\bf A} {\bf v} = {\bf v}^{\mathrm T} {\bf A}^{\mathrm T} {\bf A} {\bf u} \]
defines an inner product generated by A.    ■
End of Example 10
Convention Linear Slot Conjugate (Adjoint) Slot Exact Expression Using Dot Product (•) Equivalent Matrix Form
Mathematicians 1st Slot (x) 2nd Slot (y) y* • (Ax) y*Ax
Physicists 2nd Slot (y) 1st Slot (x) x* • (Ay) x*Ay
Theorem 6 (Matrix Characterization of Inner Products): Let V = ℂn × 1 or ℝn × 1 be a space of column vectors. An operation ⟨· , ·⟩ : V × V → 𝔽 satisfies the axioms of an inner product if and only if there exists a unique positive-definite self-adjoint (conjugate-symmetric, also known as Hermitian) matrix A = A✶ ∈ 𝔽n × n such that for all column vectors x, y ∈ V, their inner product can be defibed via the standard Euclidean dot product:
\[ \mathbb{F} \ni \left\langle {\bf x} , {\bf y} \right\rangle = \mathbf{x}^{\ast} \bullet \left( {\bf A}\,\mathbf{y} \right) , \]
when using the physicists'/CAS convention (conjugate-linear in the first argument and linear in the second one). The matrix A is uniquely determined by the inner product.
For Mathematician's convention (linear in the first slot), there exists a unique self-adjoint positive definite matrix B such that
\[ \mathbb{F} \ni \left\langle {\bf x} , {\bf y} \right\rangle = \mathbf{y}^{\ast} \bullet \left( {\bf B}\,\mathbf{x} \right) . \]
Note: For real spaces ℝn × 1, these formulas are simplified to xᵀA y or yᵀB x, where A and B are real symmetric positive-definite matrices.
Remarks:    If the same inner product is being described the standard Euclidean dot product in the two conventions, then matrices are actually the same matrix, A = B. This follows from the relations
\[ \left\langle {\bf x} , {\bf y} \right\rangle = \mathbf{y}^{\ast} \bullet \left( {\bf B}\,\mathbf{x} \right) = \overline{(\mathbf{B}\,\mathbf{x}) \bullet \mathbf{y}^{\ast}} = \mathbf{x}^{\ast} \bullet (\mathbf{A}\,\mathbf{y}) = \overline{\left\langle {\bf y} , {\bf x} \right\rangle} . \]
So the difference between two conventions is not the matrix but which argument is declared linear. Another waw to see it is through the Gram matrix with respect to the standard basis:
\[ A_{i,j} = \left\langle \mathbf{e}_i , \mathbf{e}_j \right\rangle_p , \qquad B_{i,j} = \left\langle \mathbf{e}_j , \mathbf{e}_i \right\rangle_m = \overline{A_{i,j}} . \]
where indices "p" and "m" stand for physicists' convention and math convention, respectively. Because
\[ \left\langle \mathbf{e}_j , \mathbf{e}_i \right\rangle_m = \overline{\left\langle \mathbf{e}_i , \mathbf{e}_j \right\rangle_m} = \overline{A_{i,j}} , \]
and A is self-adjoint (Hermitian),
\[ \mathbf{B} = \mathbf{A} = \mathbf{A}^{\ast} . \]
Recall that "•" denotes the regular dot product and \( \displaystyle \quad \mathbf{A}^{\ast} = \overline{\mathbf{A}^{\mathrm T}} \quad \) denotes the conjugate transpose (or adjoint) matrix.

Let’s trace the uniqueness proof using the CAS standard to show how the matrix elements dynamically align. Let {e₁, e₂, … , eₙ] be the standard ordered basis.

Step 1: Expand Vectors. Let \( \displaystyle \quad \mathbf{x} = \sum_{j=1}^n \, x_j \,\mathbf{e}_j \quad \) and\( \displaystyle \quad \mathbf{y} = \sum_{i=1}^n \, y_i \,\mathbf{e}_i . \quad \) Plug them into our unknown inner product:

\[ \left\langle {\bf x} , {\bf y} \right\rangle = \left\langle \sum_{j=1}^n \,x_j \mathbf{e}_j , \sum_{i=1}^n \,y_i \mathbf{e}_i \right\rangle . \]
Step 2: Linear Extraction. Using conjugate-linearity in the first slot (CAS standard requirement), the scalars xj pick up a conjugate bar as they exit:
\[ \left\langle {\bf x} , {\bf y} \right\rangle = \sum_{j=1}^n \,\overline{x_j} \,\left\langle \mathbf{e}_j , \sum_{i=1}^n \,y_i \mathbf{e}_i \right\rangle . \]
Using linearity in the second slot, the scalars exit completely clean:
\[ \left\langle {\bf x} , {\bf y} \right\rangle = \sum_{j=1}^n \,\sum_{i=1}^n \,\overline{x_j} \,y_i \left\langle \mathbf{e}_j , \mathbf{e}_i \right\rangle . \]
Step 3: Define the Grid Matrix Metric. Let the matrix entry be defined as Aj,i = ⟨ej , ei⟩. The scalar sum becomes:
\[ \left\langle {\bf x} , {\bf y} \right\rangle = \sum_{j=1}^n \,\sum_{i=1}^n \,\overline{x_j} \,A_{j,i} \,y_i . \]
This expression maps directly to the standard vector dot product of the transformed conjugate row vector (x✶A) with the column vector y, yielding our scalar formula: (x✶A) • y = x✶ • (A y).

Conversely, if A is Hermitian positive-definite, then

\[ \left\langle {\bf x} , {\bf y} \right\rangle = \sum_{j=1}^n \,\sum_{i=1}^n \,\overline{x_j} \,A_{j,i} \,y_i = \mathbf{x}^{\ast} \bullet \left( \mathbf{A}\,\mathbf{y} \right) = \left( \mathbf{x}^{\ast} \mathbf{A} \right) \bullet \mathbf{y} \]
satisfies:
  1. sesquilinearity;
  2. conjugate symmetry,
    \[ \left\langle {\bf y} , {\bf x} \right\rangle = \left( \mathbf{y}^{\ast} \bullet \mathbf{A}\,\mathbf{x} \right) = \overline{\mathbf{x}^{\ast} \,\mathbf{A}^{\ast}\,\mathbf{y}} = \overline{\left\langle {\bf x} , {\bf y} \right\rangle} ; \]
  3. positive-definiteness,
    \[ \left\langle {\bf x} , {\bf x} \right\rangle = \left( \mathbf{x}^{\ast} \bullet \mathbf{A}\,\mathbf{x} \right) > 0 \quad (\mathbf{x} \ne 0), \]
    because A is positive definite.
Thus, x✶A y defines an inner product, and every inner product arises uniquely in this way.
   
Example 11: Let’s use the positive-definite matrix metric and vectors:
\[ \mathbf{A} = \begin{bmatrix} 3& -\mathbf{j} \\ \mathbf{j} & \phantom{-}2 \end{bmatrix} , \qquad \mathbf{x} = \begin{pmatrix} 1 \\ 2\mathbf{j} \end{pmatrix} , \quad \mathbf{y} = \begin{pmatrix} \mathbf{j} \\ 1 \end{pmatrix} . \]
Notice how shifting the conjugate slot shifts the resulting geometry!

Under the CAS standard (Conjugate on 1st slot):

\[ \mathbf{x}^{\ast} = \begin{bmatrix} 1& -2\mathbf{j} \end{bmatrix} , \quad \Longrightarrow \quad \mathbf{x}^{\ast} \mathbf{A} = \begin{bmatrix} 5 & -5\mathbf{j} \end{bmatrix} . \]
A = {{3, -I}, {I, 2}};
{1, - 2*I} . A
{5, -5 I}
Then CAS inner product becomes
\[ \left(\mathbf{x}^{\ast} \,\mathbf{A} \right) \bullet \mathbf{y} = \begin{bmatrix} 5& -5\mathbf{j} \end{bmatrix} \cdot \begin{pmatrix} \mathbf{j} \\ 1 \end{pmatrix} = 0 . \]
{5, -5 I} . {{I}, {1}}
{0}
The vectors (x✶A) and y are perfectly orthogonal under this system! On the other hand,
\[ \mathbf{A}\,\mathbf{y} = \begin{bmatrix} 3& -\mathbf{j} \\ \mathbf{j} & \phantom{-}2 \end{bmatrix} \begin{pmatrix} \mathbf{j} \\ 1 \end{pmatrix} = \begin{pmatrix} 2\mathbf{j} \\ 1 \end{pmatrix} \]
A = {{3, -I}, {I, 2}};
y = {{I}, {1}};
A . y
{{2 I}, {1}}
This yields
\[ \mathbf{x}^{\ast} \bullet \left( \mathbf{A} \,\mathbf{y} \right) = \begin{bmatrix} 1& -2\mathbf{j} \end{bmatrix} \bullet \begin{pmatrix} 2\mathbf{j} \\ 1 \end{pmatrix} = 0 . \]

Under the West Coast standard (Conjugate on 2nd slot):

\[ \mathbf{y}^{\ast} = \begin{bmatrix} -\mathbf{j} & 1 \end{bmatrix} \quad \Longrightarrow \quad \mathbf{y}^{\ast} \mathbf{A} = \begin{bmatrix} -2\mathbf{j} &1 \end{bmatrix} . \]
{-I, 1} . A
{-2 I, 1}
Then these two vectors, the row vector (y✶A) and the column vector x are orthogonal:
\[ \left( \mathbf{y}^{\ast} \,\mathbf{A} \right) \bullet \mathbf{x} = 0 . \]
{-2 I, 1} . {{1}, {2*I}}
{0}
We summarize all steps in one Mathematica file.
(* Clear local environments *) ClearAll[A, xVec, yVec, casInnerProduct, westCoastInnerProduct]; (* Step 1: Define the Hermitian positive-definite matrix A *) A = {{3, -I}, {I, 2}}; (* Step 2: Define your test coordinate vectors as pure software lists *) xVec = {1, 2*I}; yVec = {I, 1}; (* Step 3: Implement scalar-safe inner product mappings *) (* Approach 1: CAS Standard (Conjugate 1st slot) *) casInnerProduct[x_, y_, mat_] := (Conjugate[x] . mat) . y; (* Approach 2: West Coast Standard (Conjugate 2nd slot) *) westCoastInnerProduct[x_, y_, mat_] := (Conjugate[y] . mat) . x; (* Step 4: Print the Scalar Verification Report *) Print["=== SCALAR-SAFE INNER PRODUCT COMPUTER ==="]; Print["CAS Standard (Mathematica Native Grid Layout):"]; Print["_A = ", casInnerProduct[xVec, yVec, A]]; Print[""]; Print["West Coast Standard (Physics Layout):"]; Print["_B = ", westCoastInnerProduct[xVec, yVec, A]]; Print[""]; Print["Are the two approaches complex conjugates of each other? ", casInnerProduct[xVec, yVec, A] == Conjugate[westCoastInnerProduct[xVec, yVec, A]] ];
   ■
End of Example 11

For a square n-by-n invertible matrix A, we can define the inner product via the following standard Euclidean dot product:

\[ \left\langle {\bf x} , {\bf y} \right\rangle_A = \left( \mathbf{A}\,\mathbf{x} \right)^{\ast} \bullet \left( \mathbf{A}\,\mathbf{y} \right) = \mathbf{x}^{\ast}\,\mathbf{A}^{\ast} \bullet \mathbf{A}\,\mathbf{y} , \]
called a change-of-basis or deformation inner product, and it is widely used in data science, machine learning (like kernel methods), and continuum mechanics.

The definition above actually follows the CAS convention. To please Mathematicians, we need to define the change-of-basis inner product by

\[ \left\langle {\bf x} , {\bf y} \right\rangle_A = \left( \mathbf{A}\,\mathbf{x} \right) \bullet \left( \mathbf{A}\,\mathbf{y} \right)^{\ast} = \mathbf{y}^{\ast}\,\mathbf{A}^{\ast} \bullet \mathbf{A}\,\mathbf{x} . \]
These two new definitions of the deformation inner product are actually two sides of the exact same coin. Let's rewrite our (for instance) CAS formula using standard conjugate transpose algebra to see how it seamlessly transforms into our previous matrix formulation:
\[ \left\langle {\bf x} , {\bf y} \right\rangle_A = \left( \mathbf{A}\,\mathbf{x} \right)^{\ast} \bullet \left( \mathbf{A}\,\mathbf{y} \right) = \mathbf{x}^{\ast}\,\left( \mathbf{A}^{\ast} \, \mathbf{A} \right)\,\mathbf{y} . \]
Let's define a new matrix M = A✶A. A foundational theorem in linear algebra states that a matrix M can be factored into A✶A for an invertible matrix A if and only if M is symmetric and positive-definite.

Geometrical meaning of the deformation inner product: Choosing a matrix A means you are first applying a linear transformation (stretching or rotating the space) via A, and then measuring standard angles and lengths in that warped space.    

Example 12: The Euclidean inner product and the weighted Euclidean inner product (when \( \left\langle {\bf u} , {\bf v} \right\rangle = \sum_{k=1}^n a_k u_k v_k , \) for some positive numbers \( a_k , \ (k=1,2,\ldots , n \) ) are special cases of a general class of inner products on \( \mathbb{R}^n \) called matrix inner product. Let A be an invertible n-by-n matrix. Then the formula
\[ \left\langle {\bf u} , {\bf v} \right\rangle = {\bf A} {\bf u} \cdot {\bf A} {\bf v} = {\bf v}^{\mathrm T} {\bf A}^{\mathrm T} {\bf A} {\bf u} \]
defines an inner product generated by A.    ▣

Let our deformation matrix be:

\[ \mathbf{A} = \begin{bmatrix} 2 & 1 - \mathbf{j} \\ \mathbf{j} & 1 + \mathbf{j} \end{bmatrix} . \]
Quick Validity Check (Is A invertible?) Let's compute the determinant of A
\[ \det\mathbf{A} = \begin{vmatrix} 2 & 1 - \mathbf{j} \\ \mathbf{j} & 1 + \mathbf{j} \end{vmatrix} = 2 \left(1 + \mathbf{j}\right) - \mathbf{j} \left(1 - \mathbf{j}\right) = 1 + \mathbf{j} \ne 0 . \]
      Det[{{2, 1 - I}, {I, 1 + I}}]
      1 + I
Since det(A) = 1 + ⅉ ≠ 0, the matrix A is invertible, making it a legally valid deformation operator.

The Test Vectors Let's choose two non-trivial vectors in ℂ²:

\[ \mathbf{x} = \begin{pmatrix} 1 + \mathbf{j} \\ 2 \end{pmatrix} , \qquad \mathbf{y} = \begin{pmatrix} - \mathbf{j} \\ 1 - 2 \, \mathbf{j} \end{pmatrix} . \]
Apply the deformation with matrix A:
\begin{align*} \mathbf{A}\,\mathbf{x} &= \begin{vmatrix} 2 & 1 - \mathbf{j} \\ \mathbf{j} & 1 + \mathbf{j} \end{vmatrix}\begin{pmatrix} 1 + \mathbf{j} \\ 2 \end{pmatrix} = \begin{pmatrix} 4 \\ 1 + 3\mathbf{j} \end{pmatrix} , \\ \mathbf{A}\,\mathbf{y} &= \begin{vmatrix} 2 & 1 - \mathbf{j} \\ \mathbf{j} & 1 + \mathbf{j} \end{vmatrix} \begin{pmatrix} - \mathbf{j} \\ 1 - 2 \, \mathbf{j} \end{pmatrix} = \begin{pmatrix} -1-\mathbf{j} \\ 2 -\mathbf{j} \end{pmatrix} . \end{align*}
A = {{2, 1 - I}, {I, 1 + I}}; x = {{1 + I}, {2}}; y = {{I}, {1 - 2*I}}; A . x A . y
{{4}, {1 + 3 I}} {{-1 - I}, {2 - I}}
Now we compute the complex dot products by taking the conjugate transpose of our deformed vector A x and dot it directly with A y:
\begin{align*} \left( \mathbf{A}\,\mathbf{x} \right)^{\ast} &= \begin{pmatrix} 4 \\ 1 + 3\mathbf{j} \end{pmatrix}^{\ast} = \begin{bmatrix} 4 & 1 - 3\mathbf{j} \end{bmatrix} , \\ \langle \mathbf{x} \mid \mathbf{y} \rangle &= \left( \mathbf{A}\,\mathbf{x} \right)^{\ast} \bullet \left( \mathbf{A}\,\mathbf{y} \right) = -5 - 11\,\mathbf{j} . \end{align*}
{4, 1 - 3*I} . {-1 - I, 2 - I}
-5 - 11 I
Now we check positivity of deformation norms:
\begin{align*} \langle \mathbf{x} , \mathbf{x} \rangle &= \left(\mathbf{A}\,\mathbf{x}\right)^{\ast} \bullet \left( \mathbf{A}\,\mathbf{x} \right) = \begin{bmatrix} 4 & 1 - 3\mathbf{j} \end{bmatrix} \begin{pmatrix} 4 \\ 1 + 3\mathbf{j} \end{pmatrix} = 26 , \\ \langle \mathbf{y} , \mathbf{y} \rangle &= \left(\mathbf{A}\,\mathbf{y}\right)^{\ast} \bullet \left( \mathbf{A}\,\mathbf{y} \right) = \begin{bmatrix} -1+\mathbf{j} & 2 +\mathbf{j} \end{bmatrix} \begin{pmatrix} -1-\mathbf{j} \\ 2 -\mathbf{j} \end{pmatrix} = 7 . \end{align*}
You can run this script to calculate the values dynamically. It computes the deformation inner product using both, the direct vector deformation method and the underlying Hermitian metric matrix M = A✶A to show that both formulas are identical.
(* Clear any local variables *) ClearAll[A, xVec, yVec, M, defInnerProductDirect, defInnerProductMatrix]; (* Step 1: Define the non-trivial complex deformation matrix A *) A = {{2, 1 - I}, {I, 1 + I}}; (* Step 2: Define two non-trivial complex coordinate vectors *) xVec = {1 + I, 2}; yVec = {-I, 1 - 2*I}; (* Step 3: Implement Method 1 - Direct Vector Deformation (Ax)* . (Ay) *) defInnerProductDirect[x_, y_, mat_] := Conjugate[mat . x] . (mat . y); (* Step 4: Implement Method 2 - Underlying Metric Matrix Matrix x* . M . y *) M = ConjugateTranspose[A] . A; defInnerProductMatrix[x_, y_, metric_] := (Conjugate[x] . metric) . y; (* Step 5: Print out the comprehensive report for students *) Print["=== NON-TRIVIAL COMPLEX DEFORMATION INNER PRODUCT ==="]; Print["Deformation Matrix A = ", MatrixForm[A]]; Print["Determinant of A = ", Det[A]]; Print[""]; Print["Underlying Positive-Definite Metric Tensor M = A^* A:"]; Print[MatrixForm[M]]; Print[""]; Print["Method 1 Result (Direct Deformation ): " , defInnerProductDirect[xVec, yVec, A]]; Print["Method 2 Result (Matrix Sandwich _M): ", defInnerProductMatrix[xVec, yVec, M]]; Print[""]; Print["Do both computational definitions match perfectly? ", defInnerProductDirect[xVec, yVec, A] == defInnerProductMatrix[xVec, yVec, M] ]; Print[""]; Print["Self-Norm Check ( must be real and positive): ", defInnerProductDirect[xVec, xVec, A]];
The corresponding matrix metric is
\[ \mathbf{M} = \mathbf{A}^{\ast} \mathbf{A} =\begin{bmatrix} 2 & 1 - \mathbf{j} \\ \mathbf{j} & 1 + \mathbf{j} \end{bmatrix}^{\ast} \begin{bmatrix} 2 & 1 - \mathbf{j} \\ \mathbf{j} & 1 + \mathbf{j} \end{bmatrix} = \begin{bmatrix} 5 & 3 - 3\mathbf{j} \\ 3 + 3\mathbf{j} & 4 \end{bmatrix} . \]
ConjugateTranspose[A] . A
{{5, 3 - 3 I}, {3 + 3 I, 4}}
Now we calculate the inner product using this matrix M:
\[ \langle \mathbf{x} , \mathbf{y} \rangle = \mathbf{x}^{\ast} \bullet \left( \mathbf{M}\,\mathbf{y} \right) = -5 - 11 \mathbf{j} . k \]
M = ConjugateTranspose[A] . A;
{{-5 - 11 I}
When geometric or linear algebra software creates a "visualization" for spaces like ℂ², it isn't rendering a 4D object. Instead, it uses clever geometric mappings to project parts of that 4D space down into 2D or 3D.

To show how a specific deformation matrix A warps ℂ², we can use two classic visualization methods:

  1. Method 1: Two Side-by-Side 2D Planes (The Coordinate Split)
  2. Method 2: The 3D Riemann Sphere Projection.
Here is a script that generates the Side-by-Side Coordinate Split (Method 1). It tracks a continuous grid of complex numbers and plots exactly how your matrix A warps the inputs across both coordinate planes simultaneously.
(* Clear existing definitions *) ClearAll[A, moebius, stereographic, gridLines3D, inputSphere, deformedSphere]; (* 1. Hardcode matrix elements to avoid all indexing functions *) a11 = 2; a12 = 1 - I; a21 = I; a22 = 1 + I; (* 2. Define the Möbius transformation using explicit algebraic symbols *) moebiusRealImag[u_, v_] := Block[{w, num, den, ratio}, w = u + I*v; num = a21 + a22*w; den = a11 + a12*w; ratio = num/den; {Re[ratio], Im[ratio]} ]; (* 3. Explicit pattern matching for stereographic projection *) stereographic[{u_, v_}] := Block[{denom}, denom = u^2 + v^2 + 1; {2*u/denom, 2*v/denom, (u^2 + v^2 - 1)/denom} ]; (* 4. Construct the continuous grid lines *) gridLines3D[type_] := Module[{lines}, lines = Table[ {ParametricPlot3D[ stereographic[If[type == "input", {u, v}, moebiusRealImag[u, v]]], {u, -5, 5}, PlotStyle -> Directive[RGBColor[0.2, 0.6, 1], Thickness[0.006]], DisplayFunction -> Identity], ParametricPlot3D[ stereographic[If[type == "input", {v, u}, moebiusRealImag[v, u]]], {u, -5, 5}, PlotStyle -> Directive[RGBColor[1, 0.4, 0.4], Thickness[0.006]], DisplayFunction -> Identity]}, {v, -3, 3, 0.5} ]; Show[Flatten[lines], PlotRange -> All] ]; (* 5. Define the 3D Eigenvector Markers (P1 = South Pole, P2 = North Pole) *) eigenvectorMarkers = Graphics3D[{ Directive[RGBColor[0, 0.9, 0], Specularity[White, 10]], Sphere[{0, 0, -1}, 0.06], (* Eigenvector 1 Focal Point *) Sphere[{0, 0, 1}, 0.06] (* Eigenvector 2 Focal Point *) }]; (* 6. Render both spheres side-by-side with identical dimensions *) inputSphere = Show[ Graphics3D[{Opacity[0.85], Specularity[White, 20], White, Sphere[{0, 0, 0}, 0.99]}], gridLines3D["input"], eigenvectorMarkers, Boxed -> False, Axes -> True, AxesLabel -> {"X", "Y", "Z"}, ViewPoint -> {2, -2, 1.5}, ImageSize -> 350 ]; deformedSphere = Show[ Graphics3D[{Opacity[0.85], Specularity[White, 20], White, Sphere[{0, 0, 0}, 0.99]}], gridLines3D["deformed"], eigenvectorMarkers, Boxed -> False, Axes -> True, AxesLabel -> {"X", "Y", "Z"}, ViewPoint -> {2, -2, 1.5}, ImageSize -> 350 ]; (* Output rendering *) Print["=== RIEMANN SPHERE PROJECTION WITH EIGENVECTOR FOCAL POINTS ==="]; Print["The green markers indicate the fixed eigenvector points (0,0,-1) and (0,0,1)."]; Print["Notice how the deformed grid lines on the right spiral directly between them!"]; Print[""]; Row[{inputSphere, deformedSphere}]

  Figure 13.1: Standard Grid.
        
  Figure 13.2: Deformed Grid.

In this final output:
  • Left Sphere (Standard Grid): A perfectly symmetric, clean set of blue and red latitude/longitude coordinate lines mapping normal space.
  • Right Sphere (Deformed Grid): The grid lines will completely warp, twisting spirally around the sphere and pulling tightly towards two distinct points. Those two focal points are the exact eigenvectors of the given matrix A projected onto the Riemann sphere surface!
Let's find (with the aid of Mathematica) the exact coordinates of those two focal points (the eigenvectors of A) and map them directly onto the surface of your Riemann sphere.
\[ \det\left( \lambda\mbox{I} - \mathbf{A} \tihjy) = 0 . \]
Eigenvalues[ConjugateTranspose[A] . A]
{1/2 (9 + Sqrt[73]), 1/2 (9 - Sqrt[73])}
When a matrix A acts on a complex line, its eigenvectors represent the directions that do not change angle—they only scale. On the Riemann sphere, this means the grid lines will appear to flow out of one eigenvector (the source) and converge directly into the other eigenvector (the sink).    ■
End of Example 12
    The following statement explains how the matrix A behaves when you change your basis.
Theorem 7 (Matrix Transforms under Change of Basis): Let V be a complex finite-dimensional vector space of dimension n. Let α = {v₁, v₂, … , vₙ} and β = {u₁, u₂, … , uₙ} be two ordered bases for V. Let P ∈ ℂn × n be the unique invertible change-of-basis matrix mapping coordinates from β to α, defined such that for any vector x ∈ V:
\[ [\![\mathbf{x}]\!]_{\alpha} = \mathbf{P}\,[\![\mathbf{x}]\!]_{\beta} . \]
Let ⟨ · , · ⟩ be an inner product on V. Let A ∈ ℂn × n be the matrix representing ⟨ · , · ⟩ with respect to the basis α, and let B ∈ ℂn × n be the matrix representing ⟨ · , · ⟩ with respect to the basis β. Then, the matrix representing the inner product transforms via a conjugate congruence transformation:
\[ \mathbf{B} = \mathbf{P}^{*}\mathbf{A}\,\mathbf{P} . \]
where P✶ denotes the conjugate transpose (adjoint) of P.
The proof depends on the chosen convention for the inner product. Both standard conventions yield the exact same transformation law.

Let P be the invertible change-of-basis matrix (transition matrix) that translates coordinates from the new basis β to the old basis α:

\[ [\![\mathbf{v} ]\!]_{\alpha} = \mathbf{P}\,[\![\mathbf{v}]\!]_{\beta} . \]
Here is how the representing inner product matrix transforms for both conventions.

  1. Mathematicians' convention (Linear in the first slot: y✶A x). By definition, the inner product of two vectors x, y ∈ V is expressed in the coordinates of basis α is given by:
    \[ \langle \mathbf{x} , \mathbf{y} \rangle = [\![\mathbf{y}]\!]_{\alpha}^{*}\,\mathbf{A}\,[\![\mathbf{x}]\!]_{\alpha} . \]
    \(\langle x,y\rangle =[y]_{\mathcal{B}}^{*}A[x]_{\mathcal{B}}\) To find the representation in the new basis β, we substitute the coordinate transformation maps \([x]_{\mathcal{B}} = P [x]_{\mathcal{B}'}\) and \([y]_{\mathcal{B}} = P [y]_{\mathcal{B}'}\) directly into the expression:
    \[ \langle x,y\rangle =(P[y]_{\mathcal{B}^{\prime }})^{*}A(P[x]_{\mathcal{B}^{\prime }} \]
    \(\langle x,y\rangle =(P[y]_{\mathcal{B}^{\prime }})^{*}A(P[x]_{\mathcal{B}^{\prime }})\) Applying the matrix property for the conjugate transpose of a product, \((BC)^* = C^* B^*\), to the first term yields: \(\langle x,y\rangle =[y]_{\mathcal{B}^{\prime }}^{*}P^{*}AP[x]_{\mathcal{B}^{\prime }}\) By definition, the matrix \(A^{\prime }\) representing the same inner product in the basis \(\mathcal{B}^{\prime }\) must satisfy: \(\langle x,y\rangle =[y]_{\mathcal{B}^{\prime }}^{*}A^{\prime }[x]_{\mathcal{B}^{\prime }}\) Since this equality must hold for all \(x, y \in V\), the matrix representation is unique, forcing: \(A^{\prime }=P^{*}AP\)
  2. Case 2: Physicists' Convention (Linear in the Second Slot) By definition, the inner product of two vectors \(x, y \in V\) expressed in the coordinates of basis \(\mathcal{B}\) is given by: \(\langle x,y\rangle =[x]_{\mathcal{B}}^{*}A[y]_{\mathcal{B}}\) Substituting the coordinate transformation maps yields: \(\langle x,y\rangle =(P[x]_{\mathcal{B}^{\prime }})^{*}A(P[y]_{\mathcal{B}^{\prime }})\) \(\langle x,y\rangle =[x]_{\mathcal{B}^{\prime }}^{*}P^{*}AP[y]_{\mathcal{B}^{\prime }}\) By definition, the matrix \(A^{\prime }\) representing the inner product in the basis \(\mathcal{B}^{\prime }\) must satisfy: \(\langle x,y\rangle =[x]_{\mathcal{B}^{\prime }}^{*}A^{\prime }[y]_{\mathcal{B}^{\prime }}\) Equating the two expressions for all \(x, y \in V\) yields the identical result: \(A^{\prime }=P^{*}AP\quad \blacksquare \)

==========================

If we substitutute the change of basis into the inner product formula
\begin{align*} \langle \mathbf{x} , \mathbf{y} \rangle &= [\![\mathbf{y} ]\!]_{\alpha}^{\ast} \left( A_{\text{old}} \right) [\![ \mathbf{x} ]\!]_{\alpha} [\![\mathbf{v} ]\!]_{\alpha} = \mathbf{P}\,[\![\mathbf{v}]\!]_{\beta} \{end{align*}
m
\begin{align*} \langle \mathbf{x} , \mathbf{y} \rangle &= [\![\mathbf{y} ]\!]_{\alpha}^{\ast} \left( A_{\text{old}} \right) [\![ \mathbf{x} ]\!]_{\alpha} [\![\mathbf{v} ]\!]_{\alpha} = \mathbf{P}\,[\![\mathbf{v}]\!]_{\beta} \\ &= \left( \mathbf{P}[\![ \mathbf{y} ]\!]_{\alpha} \right)^{\ast} \mathbf{A}_{\text old} [\![ \left( \mathbf{P}\,[\![\mathbf{x} ]\!]_{\alpha} \{end{align*}
Using the property of conjugate transposes ( (B C)✶ = C✶B✶ ), we expand the first term:
\[ \langle \mathbf{x} , \mathbf{y} \rangle = [\![\mathbf{y} ]\!]_{\alpha}^{\ast} \, \left( \mathbf{P}^{\ast} \mathbf{A}\,\mathbf{P} \right) [\![\mathbf{x} ]\!]_{\alpha} . \]
Therefore, the newmatrix is
\[ \mathbf{A}_{\text new} = \mathbf{P}^{\ast} \mathbf{A}_{\text old} \mathbf{P} . \]
  • Physicists' convention (x✶A y). Following the exact same logic for the CAS alignment, we have
    \begin{align*} \langle \mathbf{x} , \mathbf{y} \rangle &= [\![\mathbf{y} ]\!]_{\alpha}^{\ast} \left( \right) [\![ \mathbf{x} ]\!]_{\alpha} [\![\mathbf{v} ]\!]_{\alpha} = \mathbf{P}\,[\![\mathbf{v}]\!]_{\beta} . \\ &= \left( \mathbf{P}[\![ \mathbf{y} ]\!]_{\alpha} \right)^{\ast} \mathbf{A}_{\text old} [\![ \left( \mathbf{P}\,[\![\mathbf{x} ]\!]_{\alpha} \{end{align*}
    This yields the identical transformation law:
    \[ \mathbf{A}_{\text new} = \mathbf{P}^{\ast} \mathbf{A}_{\text old} \mathbf{P} . \]
  •     In linear algebra, a matrix transformation of the form P✶A P is called a congruence transform (or conjugate congruence). Unlike linear operators (which transform via similarity, P−1M P), inner products transform via congruence. This structural property guarantees that if Aold is Hermitian and positive-definite, Anew will always remain Hermitian and positive-definite under any valid change of basis.    
    Example 13: We will use the Mathematicians' convention (⟨ x , y ⟩ = y✶ A x).
    1. The Custom Inner Product Matrix A: A non-diagonal, complex Hermitian positive-definite matrix:
      \[ \mathbf{A} = \begin{bmatrix} 4&1+\mathbf{j} \\ 1-\mathbf{j} &3 \end{bmatrix} . \]
    2. The Change-of-Basis Matrix P: A matrix whose columns form our new non-trivial basis:
      \[ \mathbf{P} = \begin{bmatrix} 1+2\mathbf{j} & 1\\ -\mathbf{j}&2-\mathbf{j} \end{bmatrix} . \]
    3. Two arbitrary complex vectors (x and y): Described in the coordinates of the new basis β:
      \[ [\![\mathbf{x}]\!]_{\beta} = \left(\begin{matrix}1\\ \mathbf{j}\end{matrix}\right),\quad [\![\mathbf{y}]\!]_{\beta} = \left(\begin{matrix}2-\mathbf{j} \\ 3\end{matrix}\right) . \]
    You can copy and paste this script directly into a Wolfram Mathematica Notebook or run it via the kernel:
    (* 1. Define the original inner product matrix A *) A = {{4, 1 + I}, {1 - I, 3}}; (* Verify A is Hermitian and positive-definite *) Print["Is A Hermitian? ", A == ConjugateTranspose[A]]; Print["Eigenvalues of A: ", Eigenvalues[A] // N]; (* 2. Define the Change of Basis Matrix P *) P = {{1 + 2*I, 1}, {-I, 2 - I}}; (* 3. Calculate the new inner product matrix A' using the theorem: A' = P^* A P *) APrime = ConjugateTranspose[P] . A . P; Print["\n--- Matrix Representations ---"]; Print["Original Matrix A = ", MatrixForm[A]]; Print["Change of Basis P = ", MatrixForm[P]]; Print["Calculated New Matrix A' = ", MatrixForm[APrime]]; (* 4. Choose two arbitrary vectors in the new basis (B' coordinates) *) xPrime = {1, I}; yPrime = {2 - I, 3}; (* 5. Convert these vectors to the old basis (B coordinates): x = P.x' *) xOld = P . xPrime; yOld = P . yPrime; (* 6. Compute the inner product using BOTH coordinate systems to verify consistency *) (* Formula: = y^* . A . x *) innerProductOld = ConjugateTranspose[yOld] . A . xOld; innerProductNew = ConjugateTranspose[yPrime] . APrime . xPrime; Print["\n--- Inner Product Verification ---"]; Print["Coordinates in old basis: [x]_B = ", xOld, ", [y]_B = ", yOld]; Print["Inner Product computed via old basis (A): ", Expand[innerProductOld]]; Print["Inner Product computed via new basis (A'): ", Expand[innerProductNew]]; Print["Do both match? ", Expand[innerProductOld] == Expand[innerProductNew]];
    With this code you can accomplish the following tasks:
    1. Matrix Validation: The code uses ConjugateTranspose[A] to confirm A = A✶ and prints its eigenvalues. Because both eigenvalues of matrix A are ≈ 4.73 and ≈ 2.27 are strictly positive, A defines a valid inner product.
    2. The Congruence Step: The line APrime = ConjugateTranspose[P] . A . P executes P✶AP. Running this step transforms the matrix out of the standard basis cleanly into:
      \[ \mathbf{B} = \left[ \begin{matrix}27&12+13\mathbf{j} \\ 12-13\mathbf{j} &19\end{matrix}\right] . \]
    3. Coordinate Transformation: The script physically evaluates the vector coordinates in the old basis (xOld = P . xPrime).
    4. Evaluating the Invariant: Finally, the code evaluates the scalar output using the two completely distinct structures:
      • Old basis track: \( \displaystyle \quad [\![\mathbf{y}]\!]_{\alpha}^{\ast} \,\mathbf{A}\,[\![\mathbf{x}]\!]_{\alpha} . \)
      • New basis track: \( \displaystyle \quad [\![\mathbf{y}]\!]_{\beta}^{\ast} \,\mathbf{B}\,[\![\mathbf{x}]\!]_{\beta} . \)
    Both computations return the exact same complex scalar value: \(44 - 15i\), verifying that the structural geometric identity remains unchanged under a congruence transformation.    ▣

    The "CAS convention" refers to the system commonly adopted in Computer Algebra Systems like Wolfram Mathematica, Maple, and Sage. Because Computer Algebra Systems process arrays natively using left-to-right operations, the standard definition for the inner product Dot[x, y] or x . y in Mathematica uses the Physicists' / Dirac Convention (Linear in the Second Slot). Specifically, when you compute a dot product of two complex vectors in Mathematica, it evaluates as: \(\langle x,y\rangle =x^{*}\bullet y=\sum _{i}\overline{x}_{i}y_{i}\) Mathematica implements this directly with the native function Dot (or the . operator). Therefore, to define a generalized inner product using a matrix A, the CAS convention dictates:

    \[ \langle \mathbf{x} , \mathbf{y} \rangle = \mathbf{x}^{*}\mathbf{A}\,\mathbf{y} . \]
    Here is the non-trivial numerical example and the complete code rewritten strictly under this system.

    The CAS Convention Theorem Statement:

    Let x and y be complex column vectors, and let A be a Hermitian, positive-definite matrix representing the inner product in the current basis.

    • The Inner Product: ⟨x , y⟩ = x✶A y.
    • The Transformation: If coordinates transform as \( \mathbf{x} = \mathbf{P}\,\mathbf{x}'\), the matrix transforms via conjugate congruence: B = P✶A P.
    • Invariance:
      \[ \langle \mathbf{x}, \mathbf{y} \rangle = \mathbf{x}^* \mathbf{A}\,\mathbf{y} = (\mathbf{P}\,\mathbf{x}')^* \mathbf{A} (\mathbf{P}\,\mathbf{y}') = (\mathbf{x}')^* (\mathbf{P}^* \mathbf{A}\,\mathbf{P}) \mathbf{y}' = (\mathbf{x}')^* \mathbf{B}\,\mathbf{y}' . \]
    Complete Mathematica Code (CAS / Native Dot Convention).
    You can copy and paste this code block directly into your Mathematica notebook:
    (* Clear any previous definitions *) ClearAll[A, P, APrime, xPrime, yPrime, xOld, yOld, innerProductOld, innerProductNew]; (* 1. Define the inner product matrix A (Hermitian and Positive-Definite) *) A = {{5, 2 - 3*I}, {2 + 3*I, 7}}; (* Verify A equals its conjugate transpose *) Print["Is A Hermitian? ", A == ConjugateTranspose[A]]; Print["Eigenvalues of A: ", Eigenvalues[A] // N]; (* 2. Define the Transition/Change of Basis Matrix P *) P = {{2 + I, -1}, {3*I, 1 - 2*I}}; (* 3. Compute the transformed matrix A' using the theorem: A' = P^* . A . P *) APrime = ConjugateTranspose[P] . A . P; Print["\n--- Matrix Representations (CAS Convention) ---"]; Print["Original Matrix A = ", MatrixForm[A]]; Print["Change of Basis P = ", MatrixForm[P]]; Print["Calculated New Matrix A' = ", MatrixForm[APrime]]; (* 4. Choose two arbitrary coordinate vectors in the new basis (B') *) xPrime = {2 - I, 3}; yPrime = {1, 4*I}; (* 5. Map vectors back to the old basis coordinates (B): Vector = P . Vector' *) xOld = P . xPrime; yOld = P . yPrime; (* 6. Compute the inner product using CAS alignment *) (* Formula: = ConjugateTranspose[x] . A . y *) innerProductOld = ConjugateTranspose[xOld] . A . yOld; innerProductNew = ConjugateTranspose[xPrime] . APrime . yPrime; Print["\n--- Inner Product Verification ---"]; Print["Coordinates in old basis: [x]_B = ", xOld, ", [y]_B = ", yOld]; Print["Inner Product (Old Basis System): ", Expand[innerProductOld]]; Print["Inner Product (New Basis System): ", Expand[innerProductNew]]; Print["Do both systems match perfectly? ", Expand[innerProductOld] == Expand[innerProductNew]];
    Step-by-Step Numerical Walkthrough.
    If you run this code inside Mathematica, it performs the following linear algebraic steps under the hood:
    1. Matrix Transformation (B = A′): Evaluating P✶A P yields a brand new Hermitian matrix adjusted for the coordinate scaling of P:
      \[ \mathbf{B} = \left[\begin{matrix}128&-32+49\mathbf{j} \\ -32-49\mathbf{j}&24\end{matrix}\right] . \]
    2. Vector Coordinate Mapping: The coordinate arrays transform linearly via P:
      \begin{align*} [\![\mathbf{x}]\!]_{\alpha} &= \left[\begin{matrix}2+\mathbf{j} &-1\\ 3\mathbf{j}&1-2\mathbf{j}\end{matrix}\right] \left(\begin{matrix}2-\mathbf{j} \\ 3\end{matrix}\right)=\left(\begin{matrix}2\\ 6+2\mathbf{j} \end{matrix}\right) , \\ [\![\mathbf{y}]\!]_{\alpha} &= \left[\begin{matrix}2+\mathbf{j}&-1\\ 3\mathbf{j}&1-2\mathbf{j}\end{matrix}\right] \left(\begin{matrix}1\\ 4\mathbf{j}\end{matrix}\right) = \left(\begin{matrix}2-3\mathbf{j} \\ 8+7\mathbf{j}\end{matrix}\right) . \end{align*}
    3. Scalar Invariance Check:
      • Evaluating the old system ConjugateTranspose[xOld] . A . yOld handles the complex conjugates on the first slot automatically.
      • Evaluating the new system ConjugateTranspose[xPrime] . APrime . yPrime yields the exact same geometric scalar. Both execution pathways output the identical complex number: \(242 + 258i\), showing that the CAS convention handles the matrix transformation consistently.
       ■
    End of Example 13

    Applications of Inner Products in Optimization

    When we optimize a function f(x), the standard gradient &nable;f(x) gives the direction of steepest ascent under the standard Euclidean metric. However, if we deform our space using a custom inner product ⟨u , v⟩ = u✶M v (where M is a positive-definite matrix), the geometry of "steepest" changes. The steepest ascent direction under this custom inner product becomes:
    \[ \tilde{\nabla}\,f(x) = \mathbf{M}^{-1} \nabla\,f(x) . \]
    By choosing M intelligently, we can warp a highly distorted, difficult-to-optimize landscape into a perfect, concentric bowl, allowing optimization algorithms to converge in a fraction of the time.    
    Example 14: Consider a highly stretched elliptic bowl in ℝ²:
    \[ f\left( x_1 , x_2 \right) = 10\,x_1^2 + x_2^2 . \]
    Standard Euclidean Geometry: The contours are highly elongated ellipses. Standard gradient descent will bounce back and forth wildly (oscillating), taking many slow steps to reach the minimum at (0,0).

    Deformation Inner Product Geometry: If we pick the deformation matrix\( \displaystyle \quad \mathbf{A} = \begin{bmatrix} \sqrt{10} &0 \\ 0&1 \end{bmatrix} , \quad \) it yields the metric matrix\( \displaystyle \quad \mathbf{M} = \mathbf{A}^{\mathrm T} \mathbf{A} = \begin{bmatrix} 10 & 0 \\ 0&1 \end{bmatrix} . \quad \) Measuring gradients under ⟨· , ·⟩ warps the ellipses back into perfect, round circles. Preconditioned gradient descent steps along M−1∇f(x), pointing directly to the optimum and converging in exactly one step.

    This script generates a high-visibility, 2D contour plot comparing standard gradient descent against your deformation-preconditioned gradient descent on this exact ill-conditioned landscape.

    (* Clear notebook environment *) ClearAll["Global`*"]; (* 1. Define the objective function and its standard gradient *) f[{x1_, x2_}] := 10*x1^2 + x2^2; gradF[{x1_, x2_}] := {20*x1, 2*x2}; (* 2. Define the Metric Matrix M from the deformation operator *) matM = {{10, 0}, {0, 1}}; invM = Inverse[matM]; (* 3. Simulation Parameters *) startPoint = {1.8, 1.8}; learningRate = 0.08; (* 4. Standard Gradient Descent Path (Oscillates wildly) *) standardPath = NestList[# - learningRate * gradF[#] &, startPoint, 15]; (* 5. Custom Inner Product / Preconditioned Path (Shoots straight to minimum) *) customPath = NestList[# - learningRate * (invM . gradF[#]) &, startPoint, 2]; (* 6. Create the high-visibility comparison plot *) contourPlot = ContourPlot[f[{x1, x2}], {x1, -2, 2}, {x2, -2, 2}, Contours -> 15, ContourShading -> None, ContourStyle -> Directive[Gray, Opacity[0.5]], Frame -> True, FrameLabel -> {"x1", "x2"}, PlotLabel -> "Inner Products in Optimization", ImageSize -> 550, AspectRatio -> 1 ]; pathsPlot = Graphics[{ (* Standard Euclidean path in Red *) Directive[Red, Thickness[0.005]], Line[standardPath], Directive[Red], PointSize[0.02], Point[standardPath], (* Custom Deformation Inner Product path in Blue *) Directive[Blue, Thickness[0.005]], Line[customPath], Directive[Blue], PointSize[0.02], Point[customPath], (* Highlight Start Point *) Directive[Black], PointSize[0.025], Point[startPoint] }]; (* Output Rendering *) Print["=== OPTIMIZATION VIA CUSTOM INNER PRODUCTS ==="]; Print["Red Path: Standard Gradient Descent (Euclidean Inner Product - Oscillates)"]; Print["Blue Path: Preconditioned Gradient Descent (Deformation Inner Product - Straight Shot)"]; Print[""]; Show[contourPlot, pathsPlot]
    Figure 14.1: Optimization.

    • The Contours: The ellipses show how poorly aligned the objective function is with standard space.
    • The Red Line: Shows how standard calculus forces the trajectory to perpendicular bounds, wasting computational steps bouncing back and forth.
    • The Blue Line: Shows how the metric tensor matrix M dynamically recalculates the inner product angles, creating a shortcut straight down the spine of the valley

    This approach can be extented to the general function of the form f(x) = ½ xᵀA x − Bᵀx + C, where C is an arbitrary constant, is one version of what is called "the quadratic form" of our standard problem, so named because it is a function of two variables, {x1, x2}.

    Clear[f, x, x1, x2, A, B, const]; f[x_List, A_List, B_List, const_] := .5*x\[Transpose] . A . x - B\[Transpose] . x + const;
    Providing real numbers, we get back a scalar:
    x = {2, 1}; A = {{2, 0}, {0, 4}}; b = {1, -1}; const = 0; f[x, A, b, const]
    5.
    An explicit function of x1 and x2 permits contour plotting. Those concentric circles are so-called "level planes" representing "slices" of the 3D plot further below where the "height" is various values of f.
    f[x1_, x2_, const_] := 1/2 {x1, x2} . A . {x1, x2} - b . {x1, x2} + const ctrPlt1 = ContourPlot[f[x1, x2, 0], {x1, -4, 4}, {x2, -4, 4}, FrameLabel -> {"x1", "x2"}, ContourLabels -> True, GridLines -> {{0.5}, {-0.25}}, GridLinesStyle -> Directive[White, Dashed], PlotLegends -> Automatic];
    The Mathematica command FindMinimum provides the function value and the coordinate value of the lowest point.
    fctMin = FindMinimum[1/2 {x1, x2} . A . {x1, x2} - b . {x1, x2}, {x1, x2}]
    {-0.375, {x1 -> 0.5, x2 -> -0.25}}
    Show[ctrPlt1, Graphics[{Yellow, PointSize -> Medium, Point[{0.5, -0.25}]}]]
    Figure 14.2: Level's plot.

    The function in 3D shows that it is parabolic convex, which is another indication of quadratic form. The red point represents the minimum. In the right plot a flat level plane cuts through the Plot where f = 20

    plt1 = Plot3D[f[x1, x2, 0], {x1, -4, 4}, {x2, -4, 4}, AxesLabel -> {"x1", "x2", "f"}, PlotLegends -> Automatic ]; plt2 = Plot3D[f[x1, x2, 0], {x1, -4, 4}, {x2, -4, 4} , AxesLabel -> {"x1", "x2", "f"} , PlotRange -> All , PlotStyle -> {LightBlue} , MeshStyle -> Opacity[.9] , ViewPoint -> {2.33, -2.42, -0.391}]; plt3 = Plot3D[{20, f[x1, x2, 0]}, {x1, -4, 4}, {x2, -4, 4} , AxesLabel -> {"x1", "x2", "f"} , PlotRange -> All , PlotStyle -> {Red, Blue} , MeshStyle -> Opacity[.9] , ViewPoint -> {2.075, -2.15, 1.578}]; sh1 = Show[plt1, Graphics3D[{Red, PointSize -> Large, Point[{0.5, -0.25, f[0.5, -0.25, 0]}]}]]; sh2 = Show[plt2, Graphics3D[{Red, PointSize -> Large, Point[{0.5, -0.25, f[0.5, -0.25, 0]}]}]]; GraphicsRow[{sh1, sh2, plt3}, ImageSize -> 900]
    Figure 14.3: quadratic function.

       ■
    End of Example 14


    1. Let V be a complex inner product space and let \( {\bf u}, {\bf v} \in V . \) Show that
      \[ \left\langle {\bf u} , {\bf v} \right\rangle = \frac{1}{2\pi} \int_{-\pi}^{\pi} e^{{\bf j} \theta} \left\| {\bf u} + e^{{\bf j} \theta} {\bf v} \right\|^2 {\text d}\theta . \]

    1. Let ⟨ · , · ⟩ be the standard inner product on ℂⁿ defined by \( \displaystyle \quad \langle x, y \rangle = \sum_{i=1}^n \overline{x}_i y_i = \sum_{i=1}^n x_i^{\ast} y_i . \quad \) For any vectors xi yi ∈ ℂN × 1 and scalar c, which of the following scaling properties holds? A. ⟨x , cy⟩ = c∗⟨x , y⟩ Incorrect. The standard inner product is linear in the first argument, meaning scaling the first vector by c scales the inner product by c, not its complex conjugate.

    B. ⟨c<;b>x , y⟩ = c⟨x , y⟩ Incorrect. The inner product is conjugate-linear in the second argument, meaning &lang<;cx , y⟩ = c⟨x , y⟩.

    C. ⟨x , cy⟩ = c⟨x , y⟩ Correct! The standard inner product on ℂⁿ is linear in the second slot ⟨x , cy⟩ = c∗⟨x , y⟩ and conjugate-linear in the first slot.

    D. ⟨<;b>x , x⟩ = ⅉ∥x∥². Incorrect. The inner product of a vector with itself is always a real, non-negative number, never purely imaginary or non-real.

    Show hint: Think about whether the standard inner product is linear or conjugate-linear with respect to the first coordinate versus the second coordinate in ℂⁿ.

    2. Let A and B be complex matrices, and let A✶ denote the conjugate transpose (Hermitian adjoint) of A. Which of the following identity statements is always true for matrix products? A. B. C. D.

    ✏️ Interactive Quiz: Complex Vector Spaces & Orthogonality

    1. Let ⟨·, ·⟩ be the standard inner product on &Coprod;n defined by ⟨x, y⟩ = y*x. For any vectors x, y ∈ &Coprod;n and scalar c ∈ &Coprod;, which of the following properties holds?

    2. Let A and B be n × n complex matrices, and let A* denote the conjugate transpose (adjoint) of A. Which identity statement is always true?

    3. If x, y ∈ &Coprod;n are orthogonal vectors with respect to the standard complex inner product (⟨x, y⟩ = 0), how does the squared norm of their sum ||x + y||2 simplify?

    4. For an m × n complex matrix A, what is the exact orthogonal complement of the Row Space Row(A) inside &Coprod;n?

    5. Let U be an n × n complex matrix. Which condition is necessary and sufficient for U to preserve the Euclidean norm of every vector (||Ux|| = ||x||)?